# PickApps
> Discover practical AI tools, AI websites, and AI apps for writing, coding, design, marketing, research, automation, and productivity.
## Pages
- [Home](https://pickapps.org): Practical AI tool directory
- [Pricing](https://pickapps.org/pricing): One-time directory listing and placement options
- [Blog](https://pickapps.org/blog): Blog posts and articles
- [Submit an app](https://pickapps.org/submit): Submit an AI product for review or paid placement
- [Face Shape Detector](https://pickapps.org/tool/face-shape-detector): Browser-based face proportion comparison tool
- [Kalkulator MBG](https://pickapps.org/tool/kalkulator-mbg): Editable Rupiah to MBG comparison calculator
- [Contact](https://pickapps.org/contact): Contact PickApps support
## Blog Posts
### Google Pics vs. Google Photos: What’s the Difference?
URL: https://pickapps.org/blog/google-pics-vs-google-photos
Description: Learn the difference between Google Pics and Google Photos: compare AI image editing, Workspace workflows, personal photo library tools, and use cases.
If you have seen **Google Pics** appear beside Google Photos in search results, you are not alone in wondering whether it is an update, a rebrand, or simply another name for the same thing. The names are close enough to create real confusion, especially now that both products use AI to generate or alter images.
They are not the same product, and they are not designed for the same moment in your workflow.
**Google Photos** starts with a personal library: the pictures and videos you took, want to find again, organize, edit, share, or turn into a memory. **Google Pics** starts with a work task: a visual you need to create, refine, localize, or place in a document or presentation. One is primarily a photo home; the other is an AI image creation and editing workspace.
That distinction matters because it tells you where to begin. Use Google Photos when the value is already in your library. Use Google Pics when the visual still needs to be made—or when one part of an image needs to change without rebuilding the whole thing.
## Quick answer
**Use [Google Photos](https://www.google.com/intl/en_us/photos/about/)** to back up, organize, search, edit, share, and creatively reuse personal photos and videos. Its Create tools include collages, highlight videos, animations, Photo to video, Photo remix, and Video remix.
**Use Google Pics** to generate and precisely edit work visuals with Gemini-based AI. It can start from a written prompt or an imported image, lets you target an object, region, or text element, and is designed to work with Google Workspace, including Docs and Slides. It is currently a desktop experience for eligible Google Workspace and Google AI plans.
## The short version: one is a library; the other is a canvas
The easiest way to separate the two is to ask what you already have.
If you have hundreds of holiday pictures and need to find the one from a particular beach, build an album, apply a light edit, or make a short recap, Google Photos is the natural starting point. Its organizing, search, backup, sharing, and memory-oriented features are central to the product.
If you have a draft product image that needs a different background, a presentation visual with the wrong wording, or a blank space in a campaign brief that needs an original illustration, Google Pics is the better starting point. It is built around the cycle of generating, selecting, refining, and placing visual material inside a work context.
Here is the practical comparison.
| Question | Google Pics | Google Photos |
|---|---|---|
| **Primary job** | Create and precisely edit images for work | Store, find, edit, share, and revisit a personal photo and video library |
| **Typical starting point** | A prompt, a product image, a design reference, or an image in Docs/Slides | Photos and videos already backed up to a personal account |
| **Best for** | Presentations, promotional graphics, product concepts, image localization, and document visuals | Family libraries, travel albums, light photo edits, memory videos, and shareable creations |
| **AI editing model** | Select an object, region, or text element; describe the targeted change | Use guided creation tools, templates, effects, and prompt/effect-based photo or video transformations |
| **Text inside an image** | Can detect, change, restyle, and translate text elements | Not the core reason to choose the product |
| **Collaboration** | Designed for sharing and co-editing in a Workspace flow | Designed for sharing albums and memories |
| **Where it works now** | Desktop; standalone editor plus Docs and Slides integration | Web and mobile apps, with feature availability varying by device, account, and region |
| **Who can use the newest generative tools** | Eligible paid Workspace or Google AI plans | Personal Google accounts for certain generative creation features; age, region, backup, and daily-limit rules apply |
The table does not mean one product is “more powerful.” It means they solve different problems. A photo library with creative tools is not automatically a design editor; an AI design editor is not automatically a photo library.
## What Google Pics is actually for
Google describes [Google Pics](https://workspace.google.com/products/pics/) as an AI image generator and editor built into Google Workspace. You can open it in a browser, import an image from a computer, Google Drive, or Google Photos, or generate a new image from a written prompt. That is useful, but the real reason it exists is the editing layer after generation.
Rather than making you regenerate an entire image because one element is wrong, Pics lets you select a specific object or drag across a region and describe the change. You can queue up to five element-level changes before applying them. It also supports editing and translating text inside an image, along with cropping, rotating, changing aspect ratio, and undoing adjustments.
*A useful image-editing workflow starts by deciding what must remain unchanged before requesting a local change.*
*The goal is not merely a different image; it is a controlled change that preserves the parts that were already right.*
That is a different mindset from scrolling through an existing camera roll. In a work setting, the question is often not “Where is that photo?” It is “Can I make this visual fit the brief without sending it back to a designer for one small revision?”
Google Pics is also intended to reduce the handoff between image creation and document work. In [Google Docs](https://support.google.com/docs/answer/17499836?hl=en), you can select an image, choose **Edit image**, make the change in Pics, then replace the image in the document. Google Slides follows a similar path: select the image on a slide, open it in Pics, edit it, and replace it in the presentation. That may sound like a small convenience, but it removes the familiar export–rename–re-upload loop that makes visual changes feel slower than they should.
### Choose Google Pics when the job sounds like this
- “Make this product photo feel like it was shot in a warm kitchen, but keep the packaging intact.”
- “Translate the wording on this social graphic without rebuilding its layout.”
- “Generate three concept images for the opening slide, then refine the best one.”
- “Use this reference image’s color treatment on a new campaign visual.”
- “Change only the chair in this room image, not the floor, windows, or lighting.”
In other words, Pics makes sense when the image is an editable working asset—not just a record of a past moment.
## What Google Photos is actually for
Google Photos is still the place where personal imagery lives. Its value begins with backup, search, sorting, albums, sharing, and the ability to revisit a large library without manually naming every file. Its creative features extend that library rather than replacing it.
The product’s [Create area](https://support.google.com/photos/answer/6128862?hl=en) groups several ways to turn existing pictures and clips into something new. You can make animations, collages, cinematic photos, and highlight videos. The more generative options include **Photo to video**, which animates a selected still image into a short clip, **Photo remix**, which applies AI-powered templates to reimagine a photo, and **Video remix**, which can restyle or relight a short backed-up video.

*Whether the output is an animation, collage, or highlight video, the material begins with a collection of personal photos rather than a blank design brief.*

*Google Photos gathers lightweight creative actions around the personal media library rather than around a blank work canvas.*

*The useful question here is not “Can it make an image?” but “What can I make from the photos I already keep?”*
Those features make Google Photos more creative than a traditional photo storage service, but its center of gravity remains personal media. A highlight video begins with people, places, events, dates, and clips you already own. Photo to video begins with a picture from your library. Even when the result is playful or surprising, the emotional value usually comes from the original photograph.
For Photo to video specifically, [Google’s current help guidance](https://support.google.com/photos/answer/16763021?hl=en&co=GENIE.Platform%3DAndroid) says you choose an effect or write a motion, scene, or effect prompt, wait for a short result to generate, then save or share it. The feature can include audio, but availability is not universal: it requires a personal Google account, has age and regional restrictions, depends on a network connection and backed-up photos, and is subject to daily generation limits. Google also warns that AI-generated results may be unexpected or inaccurate.
*This walkthrough illustrates the kind of template-led personal photo transformation that belongs in the Google Photos workflow.*
### Choose Google Photos when the job sounds like this
- “Find the best pictures from our trip and make a shareable recap.”
- “Create a quick highlight video from last year’s birthday photos.”
- “Animate a favorite still image for fun.”
- “Apply a remix style to a personal photo and send it to friends.”
- “Keep my photo library backed up, searchable, and easy to share.”
The distinction is subtle but important. Google Photos is about **what happened and what you saved**. Google Pics is about **what you still need to make**.
## Where the overlap is real—and where it ends
The products overlap in three ways. Both can take an existing image as an input. Both offer AI-assisted changes. Both are part of the broader Google ecosystem. That overlap is exactly why their names cause confusion.
But the overlap ends at the workflow.
Suppose you took a good photo of a product on your phone. You might use Google Photos to store it, locate it later, share it with a colleague, and perhaps make a quick animated version. Once the same photo becomes the hero visual for a sales deck and needs a precise background replacement, revised wording, a new aspect ratio, and approval from teammates, the task has moved into Google Pics territory.
Conversely, a polished image created in Pics may eventually be saved to Drive or downloaded, but that does not make Pics a substitute for the life-long, searchable personal library that Photos is designed to be.
| If your real task is… | Start with | Why |
|---|---|---|
| Finding a picture from a past event | Google Photos | Library search and organization are the foundation |
| Making a birthday, travel, or family recap | Google Photos | Highlight videos and memory-based creation start with existing media |
| Editing one product object in a campaign image | Google Pics | Targeted object or region edits are the relevant control |
| Localizing text on an existing visual | Google Pics | In-image text editing and translation are built into its purpose |
| Making a collage from existing photos | Google Photos | The material is a personal collection, and the output is a memory format |
| Creating a presentation visual from a written brief | Google Pics | Prompt-led generation and Slides/Docs integration shorten the work loop |
| Trying a playful photo transformation | Google Photos | Remix and Photo to video are library-led creative tools |
## A note on Gemini and Nano Banana
Two other names add to the confusion: **Gemini** and **Nano Banana**.
Gemini is Google’s broader AI assistant and interface. Nano Banana is the name associated with Google’s Gemini-based image generation and editing model family. They are not interchangeable product names for either Google Pics or Google Photos.
A helpful way to remember the relationship is this: **a model is the engine; an app is the place where a person performs a task**. Google Pics uses Gemini-powered imaging capabilities in a workspace made for deliberate image creation and editing. Google Photos uses AI features in a personal photo-library experience. The same company can use related AI technology in both places without making the products identical.
## Access and limitations matter more than the product name
Before planning a workflow around either tool, check access. [Google Pics availability guidance](https://support.google.com/docs?p=picsavailability) lists desktop access for eligible plans, including Workspace Business Standard and Plus, Enterprise Standard and Plus, Google AI Pro and Ultra, and Google AI Pro for Education. It is not available for personal-use accounts in Germany. Generative usage has limits, and higher-resolution downloads use promotional limits faster.
Google Photos’ AI creation rules are different. Its generative tools have their own requirements around personal accounts, age, country or region, backed-up media, and daily limits. They are not offered to Google Workspace or school accounts for the set of Photo to video, Photo remix, and Video remix features described in Google’s help guidance.
That means an employee cannot assume that a personal Google Photos feature will appear inside a company Workspace account, and a consumer cannot assume that a work-focused Pics feature will appear in the Google Photos mobile app. The account type is part of the product decision.
## The decision is simpler than the names make it seem
The two products only look redundant when you describe both as “Google tools that use AI on images.” That is technically true and practically unhelpful.
Start with the asset and the outcome instead.
If you are protecting, finding, sharing, or creatively revisiting photos that matter to you, open **Google Photos**. If you are creating a visual asset for a brief, correcting a specific element, adapting an image for a document, or collaborating on a presentation-ready graphic, open **Google Pics**.
The names may remain easy to mix up. The workflows are not. One helps you make more of the memories you already have; the other helps you make the image work you still need to finish.
---
### Meta Muse Image Practical Guide: Controllable Prompts, References, and Revisions
URL: https://pickapps.org/blog/meta-muse-image-practical-guide
Description: Learn how to use Meta Muse Image for controllable AI visuals: write inspectable five-part briefs, manage multi-reference roles, and iterate across structured revision passes.
*A practical guide for creators who need more than a beautiful first draft: clearer constraints, better reference handling, and revisions that keep the image on track.*
A surprising number of AI-generated images fail in the last ten percent. The atmosphere is right, the colors are close, and the subject looks plausible—but the layout ignores the copy, the product lands in the wrong hand, the edit changes too much, or the final graphic cannot survive a second round of feedback. These are not really “style” failures. They are direction failures.
That distinction is useful when looking at **Meta Muse Image**. Its appeal is not simply that it can produce another polished picture from a text prompt. Meta positions it as an image-generation model that can plan through a request, work with multiple references, make targeted edits, and—in some situations—use tools such as web search or code to make a result more accurate. For a creator, the meaningful question is therefore not “Can it make a nice image?” It is “Can it help me turn a visual brief into something I can inspect, correct, and actually use?”
## What Meta Muse Image is—and what it is not
Meta introduced Muse Image in July 2026 as an image model from Meta Superintelligence Labs. In its [rollout announcement](https://about.fb.com/news/2026/07/introducing-muse-image-meta-ai/), Meta described access through Meta AI and a broader rollout across selected Meta surfaces; availability remains dependent on region and product surface, so it is worth checking the option presented in your own Meta AI experience.
The product is most usefully understood as a **conversational visual-workflow tool**. You can begin with an idea or an existing image, then refine the result through follow-up instructions. Meta says the model supports tasks such as removing an unwanted background subject, responding to markup or sketch-directed changes, blending several visual references, and rendering text-heavy visuals more clearly than many earlier image workflows. Its more technical [release note](https://ai.meta.com/blog/introducing-muse-image-muse-video-msl/) also describes search grounding, code-assisted generation for tasks such as plots and QR codes, iterative self-refinement, and multi-reference composition.
That does not mean Muse Image should be treated as a magical production department. It cannot replace fact checking, brand approval, rights clearance, or human judgment about whether a design will work in the place where it will be published. It is most promising when you give it a job with observable success criteria.
| If your task is… | Muse Image is worth testing when… | You still need to check… |
|---|---|---|
| A social or campaign visual | The composition, on-image text, and subject hierarchy all matter. | Copy accuracy, brand compliance, and the final crop. |
| A photo correction | You can isolate one clear change: remove, replace, recolor, or reposition. | Whether the edit altered identity, hands, reflections, or key edges. |
| A composite | Each reference has a distinct role: person, product, setting, or style. | Whether ownership and placement remain coherent. |
| A factual graphic | The visual needs a real label, chart, date, map, or code. | Every factual detail and whether a QR code actually scans. |
The model becomes less compelling when the request is fundamentally undefined. “Make it premium” is not a brief. “Create a square product-launch visual: keep the phone centered, use a dark blue surface, reserve the upper third for a six-word headline, and do not alter the device proportions” is something a creator can evaluate.

*A controllable visual brief gives the model a subject, an environment, a visual relationship, and a constraint that a human reviewer can verify.*
## The right use cases are structured, not merely decorative
The strongest creative use cases have a small amount of productive tension. You want the image to feel natural **and** preserve a specific object. You want a playful scene **and** readable copy. You want a room to look redesigned **and** maintain the geometry of the supplied photograph. The more an image must satisfy several explicit conditions, the more useful a planning-oriented workflow can be.
For example, a small business might need a product scene that keeps a real package intact while changing the season, location, and supporting props. A content team may need a clean explainer card with a readable sequence of steps. A filmmaker may need a believable keyframe before developing motion elsewhere. In every case, a one-line style prompt gives the model too much room to improvise. A brief separates what is flexible from what must not move.
This is also why Muse Image’s editing and reference features matter together. A reference image is not just inspiration. It can be evidence: *this is the bottle shape; this is the model’s wardrobe; this is the location palette; this is the layout to preserve.* The task becomes much easier to steer when each source has a named purpose.
## Write a brief that can be checked
A useful prompt does not need to be long. It needs to be **inspectable**. Before entering anything, write down the answer to five questions: What is being made? Which supplied input is authoritative? What visual grammar should the result follow? What is not allowed to change? How will you know the result is ready?
A compact prompt pattern looks like this:
```text
Task: Create a vertical launch visual for a refillable water bottle.
Authoritative input: Preserve the bottle’s silhouette, cap, label placement, and logo from Image 1.
Scene: Place it on wet black stone at dusk, with a soft teal reflection.
Composition: Bottle centered in the lower half; leave the upper third quiet for headline copy.
Constraint: Do not add text, change the label, or alter bottle proportions.
Acceptance test: The label is readable, the silhouette matches Image 1, and the upper third remains clear.
```
This pattern has a second benefit: it makes revision cheaper. If the first result is too dark, you can ask for one lighting adjustment rather than re-explaining the whole campaign. If the image has the correct mood but the bottle became distorted, you know the next instruction should reinforce the authoritative reference—not abandon the concept.
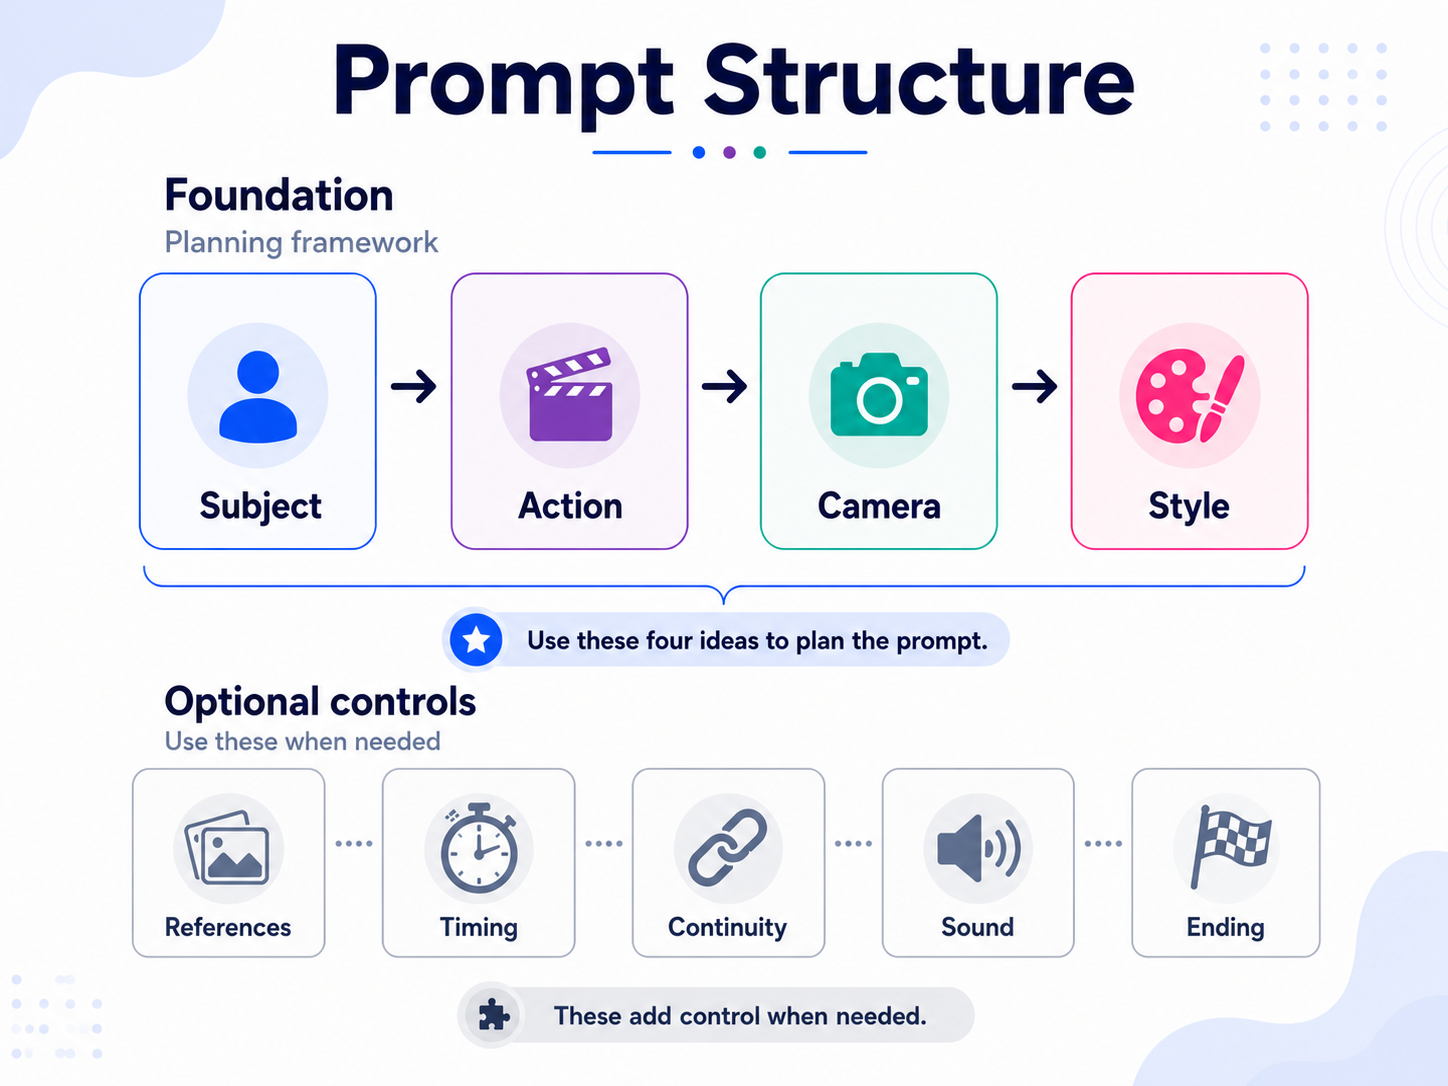
*Plan the irreducible visual decisions first. Additional detail is useful only when it removes a real ambiguity.*
The underlying discipline is simple: write nouns and relationships before adjectives. Name the object, the target image, the placement, and the allowed change. Add cinematic language after the structure is secure. This avoids a common failure mode in generative work, where a lush mood description overwhelms the one detail that mattered.
## Treat reference images as roles, not decoration
Multi-reference generation often fails because the creator uploads several strong images and assumes the intended relationship is obvious. It is not. One image may be a source of style, another may be a source of product geometry, and a third may be the canvas that should change. Unless those roles are stated, the model can merge the wrong pair, transport an object to the wrong scene, or apply the requested edit to the wrong subject.
A better instruction begins with the destination. For instance: “Edit Image 1. Take the ceramic cup from Image 2 and place it on the table in Image 1. Keep the lighting and perspective of Image 1. Do not transfer the background from Image 2.” That one sentence identifies the canvas, the donor, the requested operation, and the protected qualities.
*The key decision is not how many references you provide; it is whether the model can tell which image changes and what every other image contributes.*
For complex composites, use a short role map in the prompt rather than a paragraph of atmospheric prose.
```text
Image 1: destination canvas and camera angle.
Image 2: product geometry and label design.
Image 3: color palette and material finish only.
Requested change: place the product from Image 2 on the desk in Image 1.
Keep: Image 1 perspective and the product’s label placement.
Avoid: copying Image 3’s composition or adding any new text.
```
This approach aligns well with Muse Image’s publicly described multi-reference composition and markup-directed editing. If an adjustment is particularly local—move the object five percent to the left, remove one person, replace only a chair—annotating the relevant area can reduce ambiguity further. The annotation is not a substitute for language; it is a way to point the language at the correct part of the image.
## Revise in passes instead of asking for a perfect image
The cleanest results usually come from a sequence of modest decisions. Begin with **Pass One: composition**. Check the framing, size relationship, horizon, empty space, and object placement. Do not waste time reviewing texture before the layout works.
Move to **Pass Two: identity and legibility**. Examine product proportions, faces when relevant, key labels, signs, UI elements, and factual or numerical content. If you requested a QR code or a chart, test it outside the generation window. An image that looks correct at a glance can still fail at the one detail that matters.
Finish with **Pass Three: finish and atmosphere**. Only now should you adjust lighting, materials, color temperature, film grain, depth of field, or a more specific stylistic treatment. This order prevents a beautiful surface treatment from hiding a structural error.
Muse Image’s conversational context can be useful here because it lets the creator build on the existing visual rather than restart from scratch. Still, each follow-up should contain one clear request. If you ask to change the background, typography, person’s pose, lighting, and composition at the same time, you lose the ability to diagnose which instruction caused the unwanted change.
## Be careful with facts, provenance, and availability
Meta has emphasized accuracy-oriented features, including search grounding and code-assisted visual tasks. Those capabilities are helpful when a request involves current information, structured graphics, or machine-readable elements, but they do not transfer responsibility away from the person publishing the image. Check names, dates, price claims, maps, data labels, and any language that could influence a viewer’s decision.
Provenance deserves the same practical treatment. Meta says images generated in Meta AI and on meta.ai may carry **Content Seal**, an invisible provenance signal designed to persist through common transformations. If you need to investigate whether an image contains that signal, use Meta’s [Content Seal detection tool](https://meta.ai/identification). It is a useful signal, not a complete trust verdict. A seal does not prove every claim depicted in an image, and the absence of one does not prove a visual is authentic.
For everyday creation, Meta has said Muse Image is available through its free experience, with more generation capacity included in subscription plans. Quotas, country access, feature surfaces, and commercial conditions can change. Treat the live product interface and current terms as the decision point before building a workflow around any specific limit.
## From a resolved still to a motion brief
A well-made still is often the beginning of a video idea, not the end. Once Muse Image has helped you settle the subject, product geometry, palette, and composition, a separate image-to-video workflow can use that still as the start frame. The important boundary is that this is a **next stage**, not a claim that Muse Image itself is currently making the final video.
The motion prompt should be shorter than the image brief. Describe what the audience will see in playback order: subject, action, camera, and style. “The bottle remains fixed on the stone; condensation gathers; the camera performs a slow two-second push-in; dusk reflections ripple softly” is more actionable than “make it cinematic.”
*When you introduce motion, keep the original image’s job clear and specify the single action and camera movement that the clip must preserve.*
| A 20-minute first test | What to do | What a useful result tells you |
|---|---|---|
| Minutes 0–5 | Choose one visual with a real constraint: readable copy, an object to preserve, or an exact placement. | Whether the task is specific enough to evaluate. |
| Minutes 5–10 | Create the first draft using the five-part brief. | Whether the layout and authoritative input hold. |
| Minutes 10–15 | Make one local edit only. | Whether the conversation retains the intended context. |
| Minutes 15–20 | Review the result at publishing size and test factual elements. | Whether the output is ready to use, needs another pass, or calls for a different tool. |
The best first experiment is not an abstract beauty contest between models. It is a small job you already have: a product scene that needs an unchanged package, a social card that needs legible wording, a room concept that keeps its floor plan, or a composite with a clear source and destination. If Muse Image helps you reach a reviewable draft with fewer detours, it has earned a place in the workflow.
When you are ready to run that test, open [Meta AI](https://meta.ai/) with one concrete image brief rather than an open-ended wish. The goal is not to make the model guess what you meant. The goal is to give it enough structure to help you make the image you had in mind.
---
### How to Use HappyShrimp for Image-to-Video Soundtracks: A Practical Prompting and Timing Workflow
URL: https://pickapps.org/blog/how-to-use-happyshrimp-to-make-ai-video-music-feel-intentional
Description: Learn how to turn image-to-video edits into intentional AI soundtracks with HappyShrimp using visual score cards, energy curves, and timing-aware music prompts.
An image-to-video clip can be visually convincing and still feel unfinished. The product rotates cleanly. The portrait has a believable camera push. The city lights move. Yet the track underneath feels as if it was chosen from a different edit: the beat arrives before the motion begins, the melody crowds the product reveal, or the ending keeps talking after the picture has stopped.
That mismatch is rarely fixed by typing more genre words. It is usually a **translation problem**. A visual prompt describes what the viewer sees. A music prompt needs to describe what the viewer should *feel over time*: where energy starts, what changes, what receives emphasis, and where the clip should breathe.
This guide gives image-to-video creators a repeatable way to build that translation. The output is not a complicated music-production document. It is a compact scoring brief that you can turn into a music prompt, audition against the edit, and refine without losing the original visual idea.
*“Create a music video for our company” states an ambition, but it does not give a visual generator—or a music generator—enough creative direction.*
## The Core Principle: Score the Change, Not the Entire Clip
A short AI video does not need a miniature film score. It needs one readable relationship between **visual change** and **sonic change**. Think of the clip as a sequence of three beats rather than a block of footage:
| Beat | What the viewer sees | What the music needs to do | The question to answer |
|---|---|---|---|
| Arrival | The first frame, first motion, or first object | Establish pace and emotional temperature | Should this feel quiet, curious, polished, urgent, or playful? |
| Turn | The clearest shift in motion, framing, light, or subject attention | Add, remove, or reshape energy | What should change when the picture changes? |
| Landing | The held product, final expression, logo, or final frame | Resolve, suspend, or make space | Should the viewer feel completion or want to continue? |
The most common error is writing a track description as though the clip stays emotionally identical from beginning to end. A slow macro push and a fast product reveal might both be called “cinematic,” but they need very different energy curves. The first may need a sparse opening and a soft lift. The second may need a pulse that is already present, then a precise accent at the reveal.
Before opening a music tool, watch the video on mute and write one sentence for each beat. Do not describe every object. Describe only the information that changes the music decision.
> **Example visual score card:** A dark bottle appears in stillness; the camera glides closer as reflections move across the label; the bottle settles front-facing against a clean background.
That card already suggests a score: restrained at the start, a subtle rise during the glide, and a clean low landing when the bottle settles. It says more than “premium electronic music,” because it explains what the premium feeling must *do* inside the edit.
## Build a Scoring Brief Before You Generate Anything
A useful brief can fit in six lines. The goal is to prevent the music prompt from becoming a pile of unrelated adjectives.
| Brief field | What to write | Useful example |
|---|---|---|
| Delivery context | Where and how the clip will be watched | A nine-second vertical product reveal for a social feed |
| Visual action | The one main action in the shot | Slow push from a label detail to the full bottle |
| Emotional arc | The movement from start to finish | Stillness → anticipation → polished release |
| Energy curve | The musical density or force over time | Sparse opening, small lift, controlled ending |
| Sound palette | Instruments, texture, or vocal decision | Soft synth pad, low pulse, no lead vocal |
| Guardrails | Elements that would undermine the shot | No dramatic drop, no busy drum fill, no comedy cue |
The **guardrail** deserves more attention than it usually gets. A creator might know they want “uplifting electronic music,” but fail to say that the product needs to remain the focus. The resulting track can be technically upbeat and still be wrong because the vocal hook, percussion fill, or chorus-sized climax wins the viewer’s attention at the exact moment the picture needs clarity.
A compact scoring brief also makes iteration easier. If a result is too busy, you can change one field—energy curve or guardrail—without accidentally replacing the entire sound identity. That is much more useful than asking for a vague “less intense version.”
## From Vague Request to Directed Prompt
A music prompt should be a direct continuation of the visual brief. It should state the purpose, then the energy curve, then the sound palette, then the exclusions. This creates a sequence a generator can interpret without having to guess which detail matters most.
> Create **[sound palette]** for **[delivery context]**. Begin with **[opening energy]**; build as **[visual action]** develops; land at **[final visual beat]** with **[desired result]**. Avoid **[guardrails]**.
Here is the difference in practice.
| Too broad | Directed version |
|---|---|
| “Make cool music for a product video.” | “Create restrained instrumental electronic music for a nine-second vertical fragrance reveal. Begin with a quiet, airy synth texture and a soft pulse; add a little tension as the camera glides across the bottle; make a clean, low landing when the product settles front-facing. Avoid big drums, vocals, and a dramatic drop.” |
| “Make emotional music for a travel clip.” | “Create warm indie-folk instrumental music for a slow sunrise travel clip. Start with gentle acoustic texture and wide open space; introduce a light rhythmic lift as the camera moves forward through the landscape; end with a long, calm sustain that leaves the final wide shot breathing. Avoid trailer-style percussion and sentimental vocal lines.” |
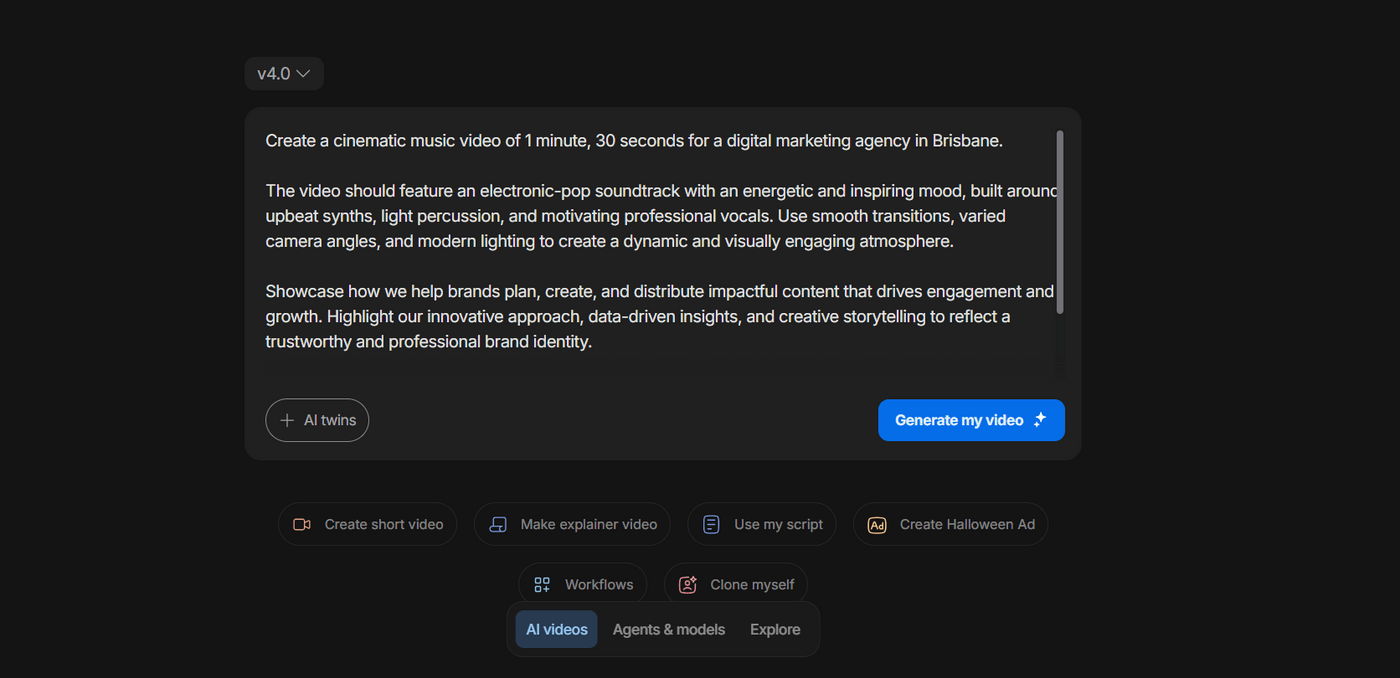
*The useful shift is not merely “more detail.” It is giving every detail a job: purpose, sound, visual pacing, and the intended viewer response.*
## Where HappyShrimp Fits in the Workflow
Once the scoring brief is clear, [HappyShrimp](https://www.happyshrimp.ai/) can act as the music-ideation step between a finished visual concept and a final edit. Its public creation page provides a place to describe the music you want to create and visibly includes `Instrumental`, `Smart Lyrics`, and `2 songs` options.
That makes its most natural role straightforward: use a written visual score card as the input for a first music direction, then audition the result against the generated clip. HappyShrimp does not need to be described as an automatic video editor, beat detector, or scoring engine for this workflow to be useful. The creator remains responsible for identifying the visual turn and final landing; the music-generation step makes it faster to test the resulting direction.
For dialogue-free image-to-video pieces, start by testing an instrumental direction. It leaves more room for motion, product detail, captions, or later sound design. If a piece genuinely needs a lyrical hook, a spoken line, or a sung point of view, develop that as a separate creative choice rather than letting a vocal appear by accident in a visual-first edit.
The visible two-song option is especially useful when you give the candidates **different jobs**. Do not ask twice for “the best track.” Ask for one restrained candidate and one forward-moving candidate. The comparison should reveal what the edit needs.
| Candidate | When to use it | Prompt adjustment |
|---|---|---|
| A: restrained | Texture, portrait, slow push, luxury detail, a final held frame | Use sparse layers, lower density, softer pulse, and a longer tail |
| B: forward-moving | Fast cuts, a sequence of small actions, before-and-after motion, a high-energy reveal | Use a clearer pulse, a gradual build, and one defined accent at the turn |
## Four Copy-Ready Prompt Recipes
The following templates are intentionally written for short image-to-video clips. Replace the bracketed details with your own scene, but preserve the relationship between action and sound.
### 1. Slow product reveal
> Create instrumental electronic music for a [duration] vertical product reveal. Begin with a quiet, glossy synth texture and a restrained low pulse. As the camera slowly pushes from [detail] to the full [product], increase anticipation without becoming loud. When the product settles [final composition], make a clean, polished landing with a short tail. Avoid vocals, dense drums, and an oversized cinematic drop.
Use this when the visual needs to feel controlled. The music should make the product more legible, not signal that a different event has started.
### 2. Fast social cut or transformation
> Create a crisp, modern instrumental cue for a [duration] social video. Start with a confident rhythmic pulse; let the energy build across [number] quick visual changes; place one sharp but clean accent at the [reveal / transformation / final cut]. Keep the ending short and decisive. Use [sound palette]. Avoid a long intro, an extended breakdown, and melodic phrases that distract from on-screen text.
Use this when the edit already has movement. Your task is not to make it busier; it is to give the cuts a consistent pulse and one memorable moment of emphasis.
### 3. Portrait or lifestyle moment
> Create an intimate [genre or palette] instrumental for a short [time of day / setting] portrait clip. Begin with open space and a gentle [instrument or texture]. As [subject action] unfolds, add only a small rhythmic lift to support the camera movement. End on a warm, unresolved sustain as the subject [final action or expression]. Avoid heavy percussion, vocals, and a sudden mood change.
Use this when the camera is doing emotional work. A close-up, a pause, and a held look often need less music than creators expect.
### 4. Travel or place-based movement
> Create atmospheric instrumental music for a [duration] [vertical / widescreen] travel clip. Begin with a spacious [instrumental palette] that matches [weather / light / location]; introduce a light sense of forward motion as the camera [camera move]; open slightly at the [wide reveal / skyline / arrival]. Keep the final image breathable. Avoid epic trailer drums and a large chorus-sized climax.
Use this when the visual opens into space. The track should widen with the picture rather than forcing a generic adventure-movie peak.
## Use the Video Prompt and the Music Prompt as Two Linked Documents
The visual prompt and the music prompt should share a few words, but they should not be copies of each other. The visual prompt tells the model how to animate the scene; the music prompt turns the animation into energy, texture, and timing.
| Visual-prompt detail | Translation for the music brief |
|---|---|
| “Slow push-in toward the subject” | Begin restrained; add intimacy or gentle tension over time |
| “Locked product rotation” | Maintain a stable pulse; avoid unexpected musical events |
| “Fast cut from dark to bright scene” | Create one clear transition accent or a noticeable lift |
| “Camera pulls back to reveal the space” | Open the harmony or reduce density to create scale |
| “Subject pauses and looks into camera” | Thin the arrangement or leave space around the pause |
| “End on a still brand frame” | Resolve cleanly, fade, or make a short quiet landing |
This is why “match the music to the video” is not specific enough. A short video can contain many visual nouns but only one or two score-worthy *changes*. Find those changes first.
*Name the sound palette and visual treatment in the same brief, but keep the energy curve simple enough to hear in one short clip.*
## A Better A/B Test: Change One Variable at a Time
If you generate two directions and neither works, do not immediately replace every adjective. Run a controlled second pass. Change one variable while retaining the rest of the score card.
| If the result feels… | Keep | Change |
|---|---|---|
| Too busy | Purpose, palette, and visual action | Reduce density; remove vocals or elaborate percussion |
| Too flat | Palette and guardrails | Add a small lift at the visual turn; define one accent |
| Too cheerful | Timing and general arrangement | Shift the emotional temperature: warm to reflective, playful to restrained |
| Too dramatic | Entry point and final landing | Remove “cinematic” shorthand; replace the drop with a controlled rise |
| Too slow for the edit | Palette and emotional intention | Ask for a clearer pulse or earlier rhythmic entry |
| Good on its own but wrong under the clip | The music direction itself | Move the edit entry a few frames; test the cut point before generating again |
The last row matters. A track can feel wrong merely because it begins too early, too late, or on the wrong frame. Before throwing it away, test a small timing adjustment inside the editing timeline. If the sound palette and energy curve now make sense, the prompt was not the problem.
## Set the Visual Format Before You Score It
Sound decisions are easier when you know the delivery format. A wide travel shot, a 9:16 product reveal, and a square social asset can use the same source image but create different pacing. A vertical crop tends to make the central subject more immediate; a wide frame has more room for environmental movement and a slower arrival. Frame rate, clip length, and the amount of movement should be selected before you commit to the music direction.
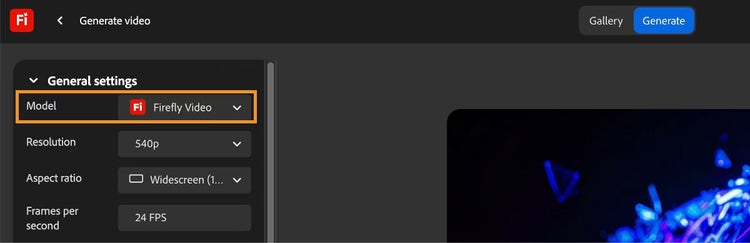
*Lock the visual format first. The more stable the output decision, the easier it is to write a useful musical energy curve.*
If you are using [ImageToVideoAI](https://imagetovideoai.tools/) or another image-to-video workflow, write the output format at the top of the score card before generating music: aspect ratio, approximate duration, one primary action, and the intended viewing context. You do not need to turn the music prompt into a technical specification. You simply need to avoid scoring a quiet, wide establishing shot as if it were a rapid vertical reveal.
## Review the Track Against Three Moments, Not the Whole Timeline at Once
When the visual and music draft are both ready, stop trying to judge the entire piece in one viewing. Check three moments in sequence.
1. **The entry:** Does the music arrive when the first visible action arrives, or does it start explaining the clip before the picture has begun?
2. **The turn:** Does the track change when the camera, motion, or viewer attention changes? It can add energy, remove energy, or simply make a small accent.
3. **The landing:** Does the final frame have enough space to register? A short fade, held chord, or deliberate stop may all work; continuous activity usually does not.
*When you review a music-video sequence, look for visual section changes and ask whether the soundtrack helps the viewer feel each change—not whether every frame has a musical event.*
For a simple product clip, the turn may be only one reflection moving across a label. For a faster montage, it may be the first hard cut or the entry of a new location. The principle stays the same: one intentional relationship is stronger than constant activity.
## Troubleshooting: What the Result Is Telling You
| Symptom | Likely cause | First fix to test |
|---|---|---|
| The music sounds generic | The brief named a mood but no visual action or arc | Add the arrival, turn, and landing in one sentence |
| The clip feels over-scored | Too many elements compete with a simple visual | Remove vocals and dense percussion; retain one pulse or texture |
| The reveal has no impact | The brief never identified the reveal as a turn | State exactly what changes at the reveal and request one controlled accent |
| The music feels late | The entry point in the timeline is wrong | Shift the track a few frames before rewriting the prompt |
| The music feels early | The visual needs silence before its first action | Delay the track or ask for a quieter opening texture |
| A track is attractive but not usable | The audio has a different emotional narrative from the picture | Keep the visual score card; change only emotional temperature or pacing |
| Every version feels unpredictable | The prompt changes too many variables at once | Lock the palette and delivery context; revise one field per test |
## When to Move Beyond a Generated First Draft
A generated track is a useful creative direction, not a universal replacement for every audio workflow. Use a more traditional production, post-production, or licensing path when the job requires frame-accurate composition, a specific human performance, precise dialogue mixing, a pre-cleared commercial track, or strict brand-audio requirements.
That boundary does not make the ideation step less valuable. On the contrary, a clean scoring brief can help a composer, editor, sound designer, or client understand the creative need much faster. “A low, restrained pulse that opens only when the skyline appears” is actionable. “Make it more cinematic” is not.
## Final Checklist Before You Publish
| Check | Pass condition |
|---|---|
| Visual action | Each clip has one primary motion or turn |
| Score card | Arrival, turn, landing, palette, and guardrails are written down |
| Prompt | It describes purpose, energy curve, sound palette, and exclusions |
| Candidate test | Two directions solve different jobs rather than repeating the same request |
| Timeline review | Entry, turn, and landing have been judged against the picture |
| Rights and review | You have confirmed the permissions and requirements for the finished production |
The best soundtrack for an image-to-video clip does not need to prove how much music it contains. It needs to make the visual decision feel inevitable. Start with the one change your viewer should feel, put that change into a six-line score card, and use HappyShrimp to audition two purposeful directions. The result is not just a track under a video. It is sound that gives the picture a beginning, a turn, and a place to land.
---
### Where DeepSeek Harness Breaks Down: A Traceable Workflow for Image-to-Video Agents
URL: https://pickapps.org/blog/deepseek-harness-image-to-video-workflow
Description: Learn why unconstrained agent prompts fail in image-to-video pipelines, how to split generation into four reviewable layers, and how to build a traceable workflow for AI video agents.
Ask an agent to “turn this product photo into an eight-second launch clip,” and it may be able to submit a generation job. The hard part begins after the job is submitted. Which first frame did it use? Did it ask for a push-in or an orbit? Why did the product drift in this version? Should the next attempt change the prompt, the model, or the source asset? And, most importantly, who decides that the result is safe and ready to publish?
That is the point many teams miss when they first evaluate **DeepSeek Harness**. Replacing a manual prompt with automation does not automatically create a reliable creative pipeline. DeepSeek describes Harness as the layer that helps an agent understand its environment, use tools, and keep operating in real-world settings. Models, tools, skills, sessions, sandboxes, storage, loops, scheduling, and the UI can all be composed as plugins in the system’s architecture. The [official overview](https://deepseek.com/harness/en/) also makes an important qualification: DeepSeek Harness is still in developer preview, and its core plugins and APIs will continue to evolve.
The practical question, then, is not “How do we make the agent generate faster?” It is this: **How do we make every generation legible at the input, checkable at the output, and recoverable when it fails?** For image-to-video work, the answer is not simply a longer prompt. It is a clear workflow contract.
## The short answer: separate one video job into four responsibilities
An image-to-video task should distinguish between creative specification, generation execution, quality review, and publishing handoff. Harness can orchestrate those responsibilities, but it should not collapse them into one open-ended request such as “make it and publish it.” Only when each stage has a defined input and exit condition does a trajectory log become genuinely useful.
| Layer | The question it answers | What should be recorded | What it should not decide on its own |
|---|---|---|---|
| Creative specification | What should this clip communicate, and how should the subject and camera move? | First-frame ID, subject constraints, action, camera move, duration, aspect ratio, style | Whether the finished clip should be published |
| Generation execution | Which approved specification should be sent to which video service? | Tool call, selected model and settings, job ID, submission time | Replacing approved constraints with a vague paraphrase |
| Quality review | Does the result preserve the subject, motion intent, and final frame? | Preview URL, checklist results, human verdict, failure reason | Treating a completed job as a usable creative asset |
| Publishing handoff | Who may download, edit, or release the asset, and are rights clear? | Approved version, intended use, owner, handoff time | Bypassing human approval to post publicly |
This structure does not reduce automation. It makes automation maintainable. DeepSeek Harness records what a model sees, as well as tool calls, tool results, subagent scheduling, and context injection in an append-only session log; its trajectory features are designed to support inspection, resuming, forking, searching, and replaying a run. That traceability only helps if the steps themselves carry clear meaning. Otherwise, the team simply gets a very long log that cannot explain a bad output.
*When subject, motion, camera, and lighting are expressed separately, a still product can be planned as a reusable moving scene instead of a one-off prompt.*
## Five places DeepSeek Harness workflows commonly get stuck
### 1. The task sounds clear to a person but has no acceptance criteria
“Make a premium product clip” is a creative direction, not an executable specification. It does not say what must remain unchanged, how the camera should move, or what the final composition needs to show. The agent is forced to fill in too many hidden decisions. When the output misses the mark, nobody can tell whether the problem came from the source image, the prompt, the model, or the camera choice.
A usable request separates **subject constraints** from **motion instructions**. Instead of writing, “Make the bottle float into frame,” define whether the bottle’s shape, label layout, and brand colors must remain intact; whether other objects are allowed; whether the camera should hold, push in, or orbit; and what the end frame must contain. Third-party prompt examples often organize a strong image-to-video instruction as **subject + action/motion + camera style + lighting**. That structure is easier for software to interpret and much easier for a team to revisit.
### 2. A successful tool call is mistaken for a successful creative result
A third-party video model returning `completed` means the job left the queue and produced a file. It does not mean the file is usable. The product may have changed proportions, text may be unreadable, hands or background objects may be broken, movement may look implausible, or the final frame may be unsuitable for the intended placement.
A generation therefore needs its own **review gate**. Begin with programmatic checks such as duration, aspect ratio, file availability, key-frame presence, and safety status. Then keep a human decision for issues that cannot be reduced to a technical state: whether brand details have drifted, whether the camera actually communicates the intended benefit, or whether the end frame is publishable. Treating review as a workflow step does not make an agent less efficient. It prevents a team from scaling incorrect creative output efficiently.
### 3. Camera direction is buried in a long prompt and cannot be compared
In image-to-video production, the most expensive revision is often not a stylistic failure. It is a movement failure. A brief intended to produce a gentle push-in turns into an abrupt zoom, or a product that should remain still drifts along with the background. This usually happens because camera language is buried among scene details, making it impossible to replace or test on its own.
Store `camera_move` as a separate field instead. It might be a controlled value such as `static`, `slow_zoom_in`, `dolly_in`, or `orbit_right`, which is then mapped to model-specific wording by a template. A team can test a different camera move without touching the first frame, subject lock, or lighting. More importantly, a failed result becomes diagnosable: did the camera instruction fail, or did the model fail to preserve the product?
*Making camera movement an independently replaceable field prevents a one-line change from altering the entire shot unpredictably.*
### 4. Plugin and version boundaries are left undefined
Composable architecture is DeepSeek Harness’s strength, but it also makes dependency management your responsibility. The project’s repository explicitly notes that it is in developer preview, is changing quickly, and will include compatibility-breaking changes. For a workflow that connects an external generation service, the risky choice is to scatter provider parameters, response fields, and business rules through agent prompts and multiple skills.
A safer design defines an internal image-to-video request and result contract. Harness works with those stable internal fields; an adapter is responsible for translating them into a particular provider’s request and response format. When a service changes, a plugin is updated, or a parameter is renamed, the adapter is the component that changes. A fixed test task can then verify that the same input still returns a previewable result and that failures still come back in a readable form.
### 5. Publishing is treated as the natural end of the tool chain
The final step is easy to overlook. Image-to-video output has more than visual-quality risk: it can involve asset permissions, likenesses, trademarks, sensitive claims, and use-specific restrictions. Even if every automatic check passes, public release should remain an explicit business action with a clear permission boundary, not the default side effect of a successful external tool call.
The DeepSeek Harness Web UI asks for approval where the active permission policy requires it. Apply the same principle to creative work: **automation can prepare candidate clips; publication should require an explicit approval.**
## A small generation contract that is actually useful
Do not begin by building an autonomous system that moves from a brief to multi-platform publishing. First, make one six-to-ten-second single-shot product clip reliable. The structure below matters not because it has many fields, but because every field can be read by a human, validated by software, and replaced independently after a failure.
```json
{
"job_id": "launch-bottle-001",
"first_frame": {
"asset_id": "approved-packshot-v3",
"subject_lock": "Preserve the bottle, label, primary colors, and proportions; do not add a second product."
},
"scene": {
"intent": "Show the metal bottle surface and condensation.",
"setting": "A dark studio with a clean background.",
"lighting": "Cool rim light from the side and rear, with a soft key light."
},
"motion": {
"subject_action": "The bottle stays stable while condensation forms slowly on the surface.",
"camera_move": "dolly_in",
"speed": "slow",
"end_frame": "Front-facing and centered, with the label fully readable."
},
"output": {
"aspect_ratio": "9:16",
"duration_seconds": 8,
"review_required": true
}
}
```
This does not mean the final model prompt must be written as JSON. Its purpose is to let Harness know exactly what it is submitting before a tool call and what it must check after receiving a result. The raw fields, rendered prompt, service settings, generation job ID, and review decision should all be written to the same searchable record.
*Structured specifications do not constrain creative work; they make sure each revision changes one identifiable variable.*
## Where Image to Video AI fits in the workflow
Only after the creative specification is approved should a team send the first frame, motion description, and output settings to an actual image-to-video service. For teams that need one place to upload a clear first frame, describe subject or camera movement, select available output settings, generate a result, preview it, and then download it, [Image to Video AI](https://imagetovideoai.tools/) can serve naturally as the **generation-and-preview** stage. It accepts JPG, PNG, and WebP source images and surfaces model-supported options such as aspect ratio, resolution, duration, or frame rate before the final preview.
One boundary is worth making explicit. This does **not** mean that DeepSeek Harness ships with an official Image to Video AI plugin, and it is not a recommendation to auto-publish results after integration. A more responsible implementation passes an approved generation contract through your own adapter or operator, translates the first-frame and motion fields into the service’s expected inputs, and writes the preview link and review verdict back to the Harness record. The generation service produces candidate clips; Harness makes the overall sequence orchestrated, explainable, and recoverable.
## Review more than “is there a video?”
Once a clip is returned, the reviewer should work through four specific questions. This converts the vague reaction—“something feels off”—into an actionable result.
| Review question | What a pass means | Where to return after a failure |
|---|---|---|
| Does the subject hold up? | The packaging, primary colors, proportions, and critical readable details do not visibly drift | Source-image quality, subject constraint, model choice |
| Is the action single-purpose and readable? | The product action is not competing with background movement or effects | `subject_action`, scene complexity |
| Does the camera match the intent? | A push-in, pan, orbit, or other move serves the planned shot | `camera_move`, speed, camera template |
| Is the ending deliverable? | Final composition, duration, aspect ratio, and usage conditions are fit for release | `end_frame`, output settings, human editing |
This is why “generate ten versions and pick one” is not a workflow by itself. More candidates can be useful, but if none has a corresponding specification version and review outcome, the next attempt still depends on memory and guesswork. Record failures as states such as `subject_drift`, `camera_mismatch`, or `end_frame_unusable`, and the next agent iteration can respond to a specific condition rather than retry blindly.
*“Generation completed” is a technical status. “Ready to deliver” is the end state of a creative workflow.*
## Start with one controlled, minimal path
If you are evaluating DeepSeek Harness, do not start by adding more tools. Pick a tightly constrained task instead: one approved product image, one camera move, one fixed aspect ratio, and one eight-second candidate clip. Wire together the specification, tool call, preview, human review, and recorded verdict before expanding the surface area.
Then add variation deliberately: a second camera move, a second scene, a shared review step, a library of approved assets, a batch queue, or a publishing integration. For every new layer, retain a task that can be run independently as a contract test. For basic setup, the [DeepSeek Harness Web UI quick-start guide](https://deepseek-harness.github.io/deepseek-harness/en/guide/quickstart) explains that a model and workspace must be configured before an agent can work through a session governed by the active permission policy.
The challenge with DeepSeek Harness is not simply whether the model is intelligent enough. The real dividing line is whether creative intent, tool execution, quality judgment, and publishing responsibility are visible as separate steps. When they are, an agent cannot mistake one lucky result for a repeatable system. And when a clip needs revision, the team finally knows what to change instead of starting from scratch.
---
### How to Use DeepSeek V4 Pro for Image-to-Video Prompts: A Practical Shot-Planning Workflow
URL: https://pickapps.org/blog/deepseek-v4-pro-image-to-video-prompt-workflow
Description: Use DeepSeek V4 Pro to turn a loose creative brief into a first-frame plan, motion direction, camera path, and preservation constraints for more controllable image-to-video generations.
The frustrating thing about a weak image-to-video prompt is not that it is short. It is that, after a bad generation, nobody can tell what to change.
A brief such as “make this skincare product look premium, cinematic, smooth, and summery” may sound specific, but it bundles the product, visual mood, subject motion, camera work, and desired finish into one vague instruction. If the label warps, the camera drifts, or the scene suddenly changes, the usual response is to pile on more adjectives. That makes the next attempt even harder to diagnose.
A more reliable approach is to turn the idea into a **shot plan** before you generate anything. That is a useful role for [DeepSeek V4 Pro](https://api-docs.deepseek.com/news/news260813). It is not a video generator; it is the planning layer that can turn natural-language direction into shot choices, motion sequencing, and constraints. DeepSeek positions V4 Pro for more demanding agent-style workflows, while its [official model card](https://huggingface.co/deepseek-ai/DeepSeek-V4-Pro-0813) documents `low`, `high`, and `max` reasoning-effort settings. In practice, that makes it useful for a two-pass process: create a fast first brief, then use deeper reasoning only where the brief contains real conflicts or fidelity risks.
## Start with one useful assumption: the first frame has already done part of the prompting
In image-to-video work, the uploaded image is not merely a reference. It is the first frame. It already establishes the subject, composition, lighting, visual style, and much of the product identity.
Your text prompt should therefore spend most of its energy on **what happens next**. Repeating that a bottle sits on black marble under golden light does little if the first frame already shows a bottle, black marble, and golden light. It is usually more effective to specify the subject action, camera path, and timing. Runway’s [image-to-video prompting guide](https://help.runwayml.com/hc/en-us/articles/48324313115155-Image-to-Video-Prompting-Guide) makes the same distinction: let the image establish the visual facts, and use the text to describe motion and camera work.
For a product demo, social clip, or concept spot, a useful shot plan only needs to answer five questions.
| Shot-plan field | What you need to decide | What goes wrong when it is missing |
|---|---|---|
| First-frame facts | Which shapes, labels, proportions, positions, and colors must stay unchanged? | The model redraws or shifts a recognizable product detail. |
| Subject action | What moves, where does it begin, and where does it end? | Every element seems to move at once, and the visual priority disappears. |
| Camera path | Is the camera pushing in, panning, orbiting, looking down, or locked off? | Several camera ideas compete and the shot feels unstable. |
| Environmental change and pace | How should steam, reflections, wind, particles, or other secondary motion develop over time? | The background becomes distracting or changes without a clear reason. |
| Preservation and exclusions | What must not change, and what must not appear? | The model “improves” the scene by adding objects or changing product details. |
> **One short clip should usually have one primary subject action and one primary camera move.** If you need a push-in, an orbit, a whip pan, an unboxing moment, a person entering frame, and a scene change, divide them into separate shots instead of asking one generation to resolve all of them.

## Use DeepSeek V4 Pro as a shot planner, not an adjective generator
Avoid asking DeepSeek to “write an amazing video prompt.” That invitation often produces a longer version of the same vague brief. Ask it to identify what is missing, what conflicts, and what the model must preserve.
Copy the prompt below into DeepSeek V4 Pro and replace the bracketed details with your own project. A low-effort pass is often enough to create an initial shot plan. If your project involves brand fidelity, sequential action, or several non-negotiable constraints, use a higher reasoning setting for the review pass. The goal is not to make the model think longer by default; it is to spend more effort only on the parts of the brief that need conflict checking.
```text
You are an image-to-video shot planner. Turn the creative brief below into an executable shot plan.
Inputs:
- First-frame content: [describe the product, person, or scene already visible]
- Creative objective: [for example: an 8-second vertical skincare ad]
- Must preserve: [bottle proportions, label placement, brand colors, etc.]
- Must avoid: [hands, extra text, a second product, abrupt cuts, etc.]
- Audience and tone: [for example: minimal, premium, fresh]
Return the following, in order:
1. Ambiguities, conflicts, and missing information in the brief;
2. A one-sentence shot intention;
3. The visual facts in the first frame that must remain unchanged;
4. Subject motion, environmental motion, camera motion, and pacing;
5. An English motion prompt for an image-to-video generator, limited to 90 words;
6. Two variants that each change only one variable;
7. The three most likely failure modes and a fix for each.
Rules: Do not invent brand elements that are not visible in the first frame. Specify only one primary camera move. If a preservation constraint conflicts with the creative objective, identify the conflict instead of forcing an answer.
```
The value of this prompt is that it asks the model to explain **why the output may be uncertain** before it writes polished prompt language. Imagine that your first frame shows a matte white serum bottle and your original brief says only “summer, refreshing, water droplets, premium.” A useful shot plan narrows that to something testable: the bottle remains still; condensation slowly forms; the camera makes a smooth macro push-in from texture detail to the full bottle; blurred leaves move slightly in the background; the label, cap, and proportions remain unchanged; no hands, text, or extra product appears.

## Turn the shot plan into the instruction a video model can execute
Do not paste the full shot-plan table into your generator. What the generation step needs most is the **motion layer**. The serum example above can become this:
```text
The camera makes a slow macro push-in toward the uploaded serum bottle as condensation beads gradually form on its surface. Soft, out-of-focus leaves sway gently in the background. Preserve the exact bottle shape, cap, label placement, colors, and proportions. Continuous seamless shot; no hands, no extra products, no text, no redesign.
```
Three choices make this prompt easier to test. The first sentence describes the camera and main subject motion. The second adds environmental motion that will not compete for attention. The final sentence handles fidelity and exclusions. It does not repeat material or lighting details that the first frame has already made clear, and it avoids untestable phrases such as “epic,” “cool,” or “stunning.”
To run the shot, open [Image to Video AI](https://imagetovideoai.tools/), upload a clean first frame, paste the motion layer into the prompt field, and adjust the aspect ratio, resolution, duration, or frame rate available for the model you choose. Start with a short clip. Review which variable is actually affecting the result before you extend the duration or change the shot. The image establishes the scene, DeepSeek removes ambiguity, and the generator turns the defined motion into a clip you can preview.
Use this short camera-motion primer as a reference before you write your next prompt:
## When a generation fails, do not rewrite everything
The fastest way to lose the thread is to replace your entire prompt after every bad result. You then have no way to tell which edit fixed the problem. Instead, map the failure back to one field in the shot plan and change only that field.
### Failure mode 1: the camera is moving everywhere
This is rarely because the prompt is not “cinematic” enough. It usually means too many camera directions are competing. Remove parallel moves such as orbit, push-in, pan, and tilt until one remains. For example, change “the camera rapidly orbits, pushes in, then tilts upward” to “the camera slowly and steadily pushes in.” If you need an orbit, make it the next shot.
Runway’s [camera-terms example library](https://help.runwayml.com/hc/en-us/articles/47313504791059-Camera-Terms-Prompts-Examples) pairs specific shot language with prompt examples and outputs. The practical lesson is simple: make one path clear before you add complexity.
### Failure mode 2: the background changes or product details drift
Return to the first-frame facts. An input image with dust clouds, strong motion blur, or a leaning composition may already imply movement. Asking the product to be completely still can create conflicting signals. Try a cleaner first frame with a more distinct subject, or remove the contradictory instruction.
Then state preservation requirements in observable terms. “Keep the label placement, bottle proportion, and cap structure unchanged” is more actionable than “do not distort.”

At this point, you can return the generated clip, a screenshot, and the original prompt to DeepSeek V4 Pro with a focused follow-up:
```text
Compare my first-frame facts, shot plan, and generated result.
Identify only one conflict that is most likely causing the failure, then provide a replacement prompt that changes only that conflict.
Do not introduce new style words, characters, camera moves, or locations.
```
This may feel conservative, but it makes iteration measurable. You know that the last test changed the camera path rather than the first frame, duration, background, and product description all at once. The next test can begin from a specific hypothesis instead of another round of guesswork.
## Use this 30-second pre-publish check
Before you download a final version, review the clip in this order. It catches many cases where the prompt looks fine on paper but the footage is not usable.
| Check | Ask yourself | First fix to try |
|---|---|---|
| Subject | Can a viewer identify the hero subject in the first two seconds? | Remove distracting environmental action and extra objects. |
| Action | Can the main action begin and finish naturally within the selected duration? | Shorten the action or increase duration; do not ask for two large actions at once. |
| Camera | Can you describe the camera as doing one main thing? | Keep one of push-in, pan, orbit, or locked-off framing. |
| Fidelity | Are the product’s proportions, label, color, and key structure still correct? | Revisit the first frame, add precise preservation terms, and remove instructions that invite a redesign. |

## Treat the prompt like a small, reviewable shoot
The original “premium, smooth, summer” brief was never a bad idea. It was simply still in creative language. Once you turn it into a shot plan, you gain a set of decisions you can actually test: what the main action is, what the main camera move is, which details the first frame must retain, and which field to change after a failed result.
DeepSeek V4 Pro handles the clarification, decomposition, and review. Image to Video AI gives you a place to execute the defined motion and inspect the clip. The next time a generation misses, resist the urge to add another string of adjectives. Choose a strong first frame, make a five-part shot plan, test one camera move, and learn from one controlled change at a time.
---
### Awesome DESIGN.md (2026): From Google's Open Format to a Demonstrable AI UI Workflow
URL: https://pickapps.org/blog/awesome-design-md-2026-guide
Description: Learn how Google DESIGN.md differs from the awesome-design-md collection, how to adapt and validate a design system file, and how to turn a finished AI UI into a clear short product demo.
An AI-generated interface can create two very convincing illusions. It looks like a product, so the team assumes it has a product. It looks cohesive, so the team assumes it has a design system. The illusion usually breaks when someone adds another page, an error state, or a mobile layout. Why is this button blue? Which spacing rule applies here? What should an empty state sound like? What happens when a generation fails?
**The point of DESIGN.md is not to give an AI another instruction such as “make it look like a well-known brand.” Its job is to turn the design decisions hidden inside a screenshot into a design contract that both people and agents can read.** Once a static interface is the starting point, the next two jobs are to make it repeatable and to make it easy to explain.
> The practical thesis of this guide is simple: treat `awesome-design-md` as a library of design decisions to study and adapt, not as a one-click brand-cloning kit. Once your static UI is stable, use a concise video to show the design logic in motion.
## First, clear up the naming: Google DESIGN.md and awesome-design-md are not the same thing
These two names are often mentioned together, but they do different jobs. In April 2026, Google Labs open-sourced the draft **DESIGN.md specification** from Stitch: a self-contained, plain-text representation of design rules. Its purpose is to help agents understand why a color exists, how components should behave, and how visual choices can be checked against constraints such as accessibility. [Google’s announcement](https://blog.google/innovation-and-ai/models-and-research/google-labs/stitch-design-md/) emphasizes that the format can move across tools and platforms, while the [official specification](https://github.com/google-labs-code/design.md/blob/main/docs/spec.md) defines it as a plain-text expression of a brand and product’s visual identity.
[VoltAgent’s awesome-design-md](https://github.com/VoltAgent/awesome-design-md), by contrast, is a community-maintained reference collection. It documents the design languages of familiar developer-focused products as readable DESIGN.md examples, with preview pages alongside them. In short, Google provides a **format and direction**; awesome-design-md provides **material you can inspect and learn from**.
| What you are looking at | The problem it actually solves | What it is not |
|---|---|---|
| Google’s DESIGN.md specification | How to express design rules in a form that people and agents can inspect | A fixed visual theme or a configuration every tool must support verbatim |
| Google Stitch | How design rules can be imported, exported, and used across projects | The only product capable of reading DESIGN.md |
| The awesome-design-md collection | How established products make decisions about color, type, components, and space | A template library to copy without thought |
| Your project’s DESIGN.md | How to preserve your product’s visual reasoning as reusable constraints | A written transcription of a single screenshot |
That distinction matters. If you treat the collection as a skin generator, the first screen may look familiar while every later screen falls apart. If you treat it as a record of design decisions, it can help your team establish its own visual boundaries much faster.

## Why an AI UI workflow needs DESIGN.md in 2026
In a conventional handoff, Figma files, component libraries, and conversations collectively preserve design memory. Once AI participates in interface production, there is another memory problem: the model has to re-decide color, density, borders, hierarchy, and tone every time it generates. When those decisions only exist in a handful of reference images, the result depends too heavily on the prompt of the day and becomes difficult to review.
DESIGN.md makes that memory explicit. A good file does not need to read like a design-theory paper, but it should let a reader answer four questions: **What should this product feel like at first glance? How is information layered? How do components change across states? Which changes are never acceptable?**
The awesome-design-md README commonly organizes its examples around visual atmosphere, semantic color, typography, component styling, layout principles, depth and elevation, do’s and don’ts, responsive behavior, and agent prompt guidance. The value of that structure is not that every section must be exhaustive. It is that it covers the information most likely to disappear when a UI moves from “looks good” to “behaves consistently.”
## Do not choose the example that looks most similar; choose the one that matches your product problem
When people open the collection, the first question is often, “Does my product look more like Stripe or Linear?” That is rarely the strongest starting point. Ask instead: “What kind of information is my user handling? Is it dense or lightweight? Are they comparing, creating, monitoring, or completing a transaction?”
A high-frequency B2B console needs you to study scan paths, data density, status color, and shortcut behavior. A consumer creative tool needs you to study onboarding rhythm, breathing room, emotional tone, and how work is displayed. Both could use dark surfaces and rounded cards; their design systems would still be based on entirely different reasons.
| Design question to inspect first | What to find in a reference example | What to preserve in your own product |
|---|---|---|
| Information density | How much judgment fits in one view; how tables, filters, and sidebars coexist | The scan rhythm and information priority, not a copied layout |
| Brand atmosphere | Color proportions, whitespace, contrast, and the frequency of decorative elements | Your own emotional keywords and contrast rules, not the original brand colors |
| Component behavior | How buttons, inputs, and cards change when hovered, selected, or disabled | The logic between states and the strength of feedback |
| Reading hierarchy | The relationship among headings, explanations, data, and calls to action | The order in which users should understand the page |
| Responsive behavior | What collapses, moves, or disappears on small screens | Task priority, rather than a shrunken desktop layout |
A useful rule follows: **borrow the structure, not the identity.** You may learn that the primary action deserves the only high-saturation color, or that supporting text should never compete with primary data. You should not import another company’s brand palette, signature visual motifs, voice, or product language into your own UI.
## Turn one reference example into your own design baseline in three passes
Reading an entire DESIGN.md in one sitting often leaves you with vague impressions: “clean,” “polished,” or “futuristic.” A more reliable approach is to make three passes, each producing a different conclusion that you can verify.
### Pass 1: Translate the visual intent instead of copying adjectives
Start with a one-sentence visual thesis. It must be specific enough to rule choices out; “modern, professional, and clean” does not qualify because it could describe almost any product. “Keep the creative flow lightweight, while making generation status and rights information unmissable” is much more useful because it guides actual decisions.
Next, rewrite the reference example’s color and hierarchy choices as semantic roles of your own: page background, primary surface, weak divider, primary action, success, risk, and low-priority text. Notice that these are **roles**, not swatches. You can iterate on exact values later. If roles are confused, every subsequent screen will be confused too.
### Pass 2: Add states and boundaries to every important component
AI can often make a convincing default state and then overlook the states that matter in a real product: an empty input, a failed request, insufficient permissions, changed pricing, or a job in progress. Your DESIGN.md should describe high-frequency components as a state chain, not merely a static appearance.
The following excerpt is not an official required template. It is a practical starting format for a new project because it keeps visual judgment and interaction boundaries in the same place.
```md
## Primary action
- Role: advance the user’s one primary task; never use it for a secondary link.
- Default: high-contrast fill; concise verb-led label; clear breathing room around the control.
- Hover / focus: strengthen brightness or outline without shifting the brand hue; keep focus visible.
- Disabled: lower emphasis while preserving legibility; never make it look clickable.
- Loading: preserve the button’s size and label position; show progress without causing layout shift.
## Empty states
- Explain why this area is empty before offering one low-friction next step.
- Do not use illustration to hide a missing explanation; if a task cannot be completed, state why.
```
### Pass 3: Write down what must not happen
Visual appeal is not the whole point of DESIGN.md. The rules that cut rework are often the negative constraints: do not use two equally strong primary CTAs on one page; do not put important status information in low-contrast gray text; do not hide form errors in the name of minimalism; do not treat mobile as a compressed desktop screenshot.
These rules can be plain, but they must be testable. “Keep the interface restrained” is much less useful than: “A marketing view may contain at most one high-saturation filled CTA per viewport, except during payment or a destructive-action confirmation.”
## Validation: stop asking “does it look right?” and ask “does it still work on another page?”
The first DESIGN.md test should not be another landing page. Ask an agent to create a page with pressure: an empty activity history, an upload flow with errors and retries, a mobile filter drawer, or a settings view with much denser information. If the rules only hold on the homepage, you have a moodboard. If hierarchy and state logic remain intact across different tasks, you are getting closer to a design system.
A small validation matrix is enough to expose most gaps.
| Test page or state | Do not check only | Check this instead |
|---|---|---|
| New-user empty state | Whether the illustration is attractive | Whether the next step is clear and the product tone remains consistent |
| Generating or loading state | Whether it has animation | Whether feedback is stable, the layout stays still, and waiting is explained |
| Error or insufficient-permission state | Whether red is prominent enough | Whether the user understands the cause, keeps their work, and can recover |
| Dense list or table | Whether the screen feels “premium” | Whether important data can still be scanned and the primary action is not buried |
| Mobile view | Whether every desktop element survives | Whether the user’s most important task becomes easier to complete |
This is where you discover what must be written back into the file: perhaps semantic status colors, narrow-screen priorities, or limits on how many CTAs can appear. **The compounding benefit of the collection comes from writing failures back into the rules.**
## Once the static design passes, turn it into a short video that explains one thing well
After an interface is stable, design review and product launch work often hit a different kind of friction. A static image cannot show where attention should travel, how a new task begins, or what a completed generation looks like. At this stage, a short video does not need to teach the entire product. It only needs to make one important action visible.
A general AI video-prompt structure can be written as “camera movement + scene + action + details.” [Runway’s video-prompt guide](https://runway.com/resources/ai-video-prompting-guide) likewise recommends choosing one primary action and defining the camera clearly. For UI demonstrations, both the camera and the action should be even more restrained: the screen is the subject, and the motion should guide attention rather than turn the interface into a visual-effects reel.
Use the following working prompt as a starting point, then revise it to fit your actual screen, brand language, and workflow.
```text
6-second product-interface demonstration. Use the uploaded interface as the exact visual reference: keep all text, brand colors, icons, grid, button locations, and information hierarchy unchanged.
The camera slowly moves toward the primary action area. Show one clear press on the “Generate” button, then let the result card appear smoothly.
Keep the movement restrained, stable, and professional. Do not add new text, controls, people, products, or dramatic transitions. Do not warp interface text or icons.
```
If you already have a key screen validated through DESIGN.md, you can upload it to [Image to Video AI](https://imagetovideoai.tools/), describe the subject movement, camera path, and mood, and then select the aspect ratio, resolution, duration, and frame rate for the channel where the clip will appear. In this workflow, the tool is not designing the UI for you. It is turning an approved static design into a previewable, downloadable short demonstration. DESIGN.md protects the visual logic; the video makes that logic legible to people who are reviewing, presenting, or discovering the product.
The point is not to make the screen move more. It is to make the motion **more controllable**. Split your prompt review into four checks:
| Prompt element | What to specify in a UI demonstration | Why it matters |
|---|---|---|
| Visual anchor | The exact screen and area that should remain the reference | Prevents the model from enlarging or inventing irrelevant visual elements |
| Camera | A slow push, a gentle pan, or a locked shot—choose one | Directs attention without interrupting information reading |
| Primary action | One click, one progress change, or one result card appearing | Reduces state confusion and the risk of warped text |
| Elements to preserve | Copy, icons, colors, layout, and component positions | Protects the design decisions already approved in DESIGN.md |
## Three common mistakes—and the more reliable alternative
**Mistake 1: treating the reference collection as a brand-cloning library.** A stronger approach is to annotate every borrowed idea: what you borrowed, why it fits, and how it becomes your own. If you cannot answer the last question, do not put the decision into your DESIGN.md.
**Mistake 2: teaching the agent only colors and border radii.** A stronger approach is to record states, hierarchy, whitespace, and non-negotiable boundaries first. Color is only one rule. The consistency users feel usually comes from feedback as they move through a task.
**Mistake 3: adding too much motion just to make a demo feel impressive.** A stronger approach is to identify the one question the clip must answer: does it guide a first generation, reveal a completed result, or emphasize one setting? Keep only the camera movement and interaction that serve that answer. A short video should lower the cost of understanding, not add visual noise.
## From “looks similar” to “reusable and explainable”
The most valuable lesson in awesome-design-md is not the number of recognizable products it documents. It is the reminder that every interface that “just looks right” is built from decisions that can be named. Turn those decisions into your own DESIGN.md, validate them across pages and states, and then use a restrained short video to explain one key task when you need to bring more people into the conversation.
That is how AI stops guessing at your taste from scratch in every prompt. It starts working from a set of design rules that can be discussed, revised, and shown. That is the part of DESIGN.md worth investing in during 2026.
---
### How to Use Image to Image AI Without Losing What Already Works
URL: https://pickapps.org/blog/how to use image to image ai
A first image is rarely a finished asset. It may have the right product angle but the wrong season. It may have a convincing portrait but an unusable background. It may already contain the beginning of a campaign, yet still need versions for a landing page, a social placement, a presentation deck, and the opening frame of a short video.
That is the useful promise of image to image AI. You do not begin with an empty prompt box and hope the model guesses your intent. You begin with a visual decision that already works, then ask for a controlled change.
The goal is not to create a completely different image. The goal is to make a better next version of the same visual idea.
## Begin With a Source That Has a Clear Job
Image to image AI performs best when the input already gives you something worth protecting. A rough product shot, a location photo, a concept sketch, or an approved campaign still can all work. What matters is that the subject is readable and the image has a deliberate visual anchor.
For a product, that anchor may be the silhouette, label placement, camera angle, or color family. For a portrait, it may be the face, hairstyle, pose, and perspective. For an interior concept, it may be the room layout, window position, daylight direction, and sense of scale.
A source image does not need to be perfect. It does need to make one important decision for you. If the product angle is right, keep it. If the person feels natural in the frame, protect that pose. If the room already has the right proportions, do not invite the model to redesign the geometry by accident.
This is where many generations go wrong. The prompt asks for a beautiful new look but never identifies the visual information that cannot drift. The result may be attractive, yet still fail because it no longer looks like the product, person, or composition you approved.
## Separate What Must Stay From What May Change
Before generating, make four decisions in plain language.
First, name the details that must remain fixed. That could be a bottle shape, a front label, a human face, a hand position, a room layout, or the negative space reserved for a headline.
Second, name one visual direction to explore. Choose the background, the lighting, the season, the styling, the material treatment, or the overall mood. Do not change all of them at once.
Third, define the finish. Tell the model whether the image should become a calm ecommerce hero, a polished editorial still, a product campaign visual, or a social asset designed to hold attention in a small crop.
Finally, name the errors you cannot accept. No altered packaging text. No extra products. No changed face. No distorted hands. No unrelated logos.
That structure gives the model a useful sequence. Protect the identity of the image. Make one meaningful change. Define what finished quality looks like. Then set the boundaries.
Here is a practical product brief.
```text
Keep the bottle shape, cap, front label, and three quarter camera angle from the reference image.
Move the product onto a pale limestone surface with soft morning light from the left and a quiet shadow from a nearby plant.
Create a wide ecommerce hero image with clean negative space on the left, realistic reflections, and a restrained wellness brand mood.
Do not add props, change the packaging text, alter the logo, or distort the glass.
```
The useful part is not the limestone or the plant shadow. It is the early instruction to preserve the bottle shape, label, and camera angle. That gives the creative direction a stable surface to work on.
## Change One Major Variable Per Pass
It is easy to see why people try to change everything in one generation. You have a source image and a long wish list. You want a new background, new lighting, a stronger mood, new props, a different lens feeling, cleaner typography space, and a fresh color grade.
That is often too much to ask from one pass.
A more reliable workflow changes one major variable at a time. Start with the background. Then test lighting. Then explore material treatment or camera mood. Every pass should answer a clear question. Does this setting make the product feel more premium? Does this light better suit the campaign? Does this crop still leave room for the message?
You gain more than a collection of options. You gain a record of cause and effect. When one result works, you know what changed. When it does not, you can revise one decision without throwing away the whole direction.
In diffusion based image workflows, the amount of change is also a creative control. Lower strength settings generally retain more similarity to the initial image. Higher settings give the model more freedom to depart from it. At the extreme, a setting of 1.0 can largely ignore the starting image.[1](https://huggingface.co/docs/diffusers/en/using-diffusers/img2img "Hugging Face Diffusers Image to Image")
You do not need a universal number. Models expose their controls differently. The practical rule is enough. When source structure matters, begin conservatively. When you intentionally want to replace the visual direction, allow more freedom.
## Use a Preservation Brief for Targeted Edits
Some assignments do not need a full restyle. You may only need to remove one object, replace a background, introduce a new prop, or clean an image before it enters a deck.
For these tasks, a preservation brief is more useful than a long mood description. State exactly what should change. Then name the nearby visual relationships that must remain coherent. A new background should respect the original light direction, focal length, depth of field, and contact shadows. A new object should have the correct scale, perspective, and point of contact.
```text
Replace only the background behind the reference subject with a warm late afternoon bookstore interior.
Keep the subject’s face, hair, jacket, pose, hands, camera angle, and expression unchanged.
Match the original lighting direction and color temperature. Keep the same shallow depth of field and realistic floor reflections.
Do not change the clothing, body proportions, or any object already held by the subject.
```
The evaluation becomes much clearer. You are no longer asking whether the image looks beautiful in the abstract. You are checking whether the edit obeyed the brief.
## Name the Destination Before You Generate
A vague request for a better version leads to vague output. Name where the image must go before you generate it.
Call it the autumn landing page hero, the brighter social variant, the concept board visual, the vertical story crop, or the clean opening frame for animation. A named use case forces decisions about aspect ratio, crop, negative space, and what must remain legible.
A visual can look impressive when viewed full screen and still fail in its real placement. Test it at the target size. Check whether the subject is still recognizable. Confirm that a headline can sit where it needs to sit. Make sure the visual direction remains clear after the image loses most of the screen.
## Run a Small Comparison Loop
Creative teams often lose time after generation. They make twenty variations, open them side by side, and find that none of them can be explained or repeated.
A small comparison loop is easier to use. The first pass checks structural fidelity. Is the subject accurate? Does the composition still hold? Are labels, faces, and important objects intact?
The next pass checks the visual direction. Did the new light, location, or styling actually move the image somewhere useful? The final pass checks production readiness. Can the result work at the intended crop, with the intended copy space, and in the intended brand context?
Once you have a clear reference and a specific change to test, a workspace such as [Image to Video AI’s Image to Image tool](https://imagetovideoai.tools/image-to-image) becomes a natural execution step. Its reference guided workflow is designed for restyling, redesigning layouts or backgrounds, making controlled variations, and polishing details. It can also carry a selected still into an image guided video workflow when the image needs to become more than a static asset.
Bring a brief, not just an image. Upload the source. State what must remain recognizable. Change one variable. Compare the result with the reference before moving to another direction.
## Carry a Proven Still Into Motion
A successful image to image result can become a stronger starting frame for animation.
This is especially helpful for short product ads, concept trailers, and social clips. Instead of asking a video model to solve the subject, setting, lighting, and movement all at once, establish the still image first. When the subject and art direction are stable, the motion prompt has a simpler job. It can focus on what moves, how the camera travels, and what should stay calm.
A final still is not merely a deliverable. It is a decision you have already solved. Carry that decision into the next medium, and you reduce the number of creative choices that have to be rediscovered from scratch.
## Check Before You Publish
Before an image leaves the creative workspace, ask four questions. Is the subject still accurate? Is the requested change obvious? Does the image work in its real placement, not only at full screen size? Do you have the right to use the reference image, brand assets, people, and output in the intended context?
Image to image AI is not the right tool for every correction. If the task requires exact label edits, legally critical text, or precise engineering geometry, conventional design and retouching tools remain safer. But for controlled variation, art direction exploration, and turning one promising image into a family of useful assets, it gives you a valuable capability.
You can keep the decision that already worked and continue the work from there.
---
### 7 Best AI Product Photography Tools for E-commerce in 2026
URL: https://pickapps.org/blog/ai-tools-for-product-photography
*AI product photography works best when it keeps the product truthful while changing the setting around it.*
A beautiful AI product image is not automatically a useful product image.
That distinction matters when you sell online. A generic image generator may create a dramatic scene, but it can also change the shape of a bottle, invent a zipper, blur a logo, remove an accessory, or show a color that your customer will never receive. Those errors are not small design flaws. They can lead to disappointed buyers, returns, and a loss of trust.
The best AI product photography tools solve a more practical problem: they help a small team create **accurate, consistent, platform-ready images** without booking a new shoot every time a product, campaign, or season changes.
This guide is designed to help you choose a tool by the job you actually need to complete. It does not rank products solely by how impressive their demo images look. Instead, it separates catalog cleanup, creative lifestyle scenes, apparel imagery, large-volume enhancement, and art-directed campaigns—because each job calls for a different kind of AI.
> **Our editorial recommendation:** Start with **Photoroom** if you need faster catalog production, **Pebblely** if you need lifestyle scenes, **Flair** if your brand team needs art direction, **Claid** if you need automated image enhancement at scale, and **insMind AI Virtual Model** if you sell apparel.
## Quick decision table
If your main problem is…Start withWhy it is the best fitDo not choose it first when…Removing backgrounds and preparing many SKU images quickly**Photoroom**It combines background removal, resizing, batch editing, brand assets, and workflow automation.You need highly art-directed campaign scenes with precise prop placement.Turning one clean product cutout into social-ready lifestyle imagery**Pebblely**It is purpose-built for generating varied product scenes and backgrounds from a product image.Your source image is blurry or the product label must remain perfectly legible at close range.Building a campaign with exact props, composition, and brand styling**Flair**Its canvas-based workflow lets you stage a scene before AI renders it.You only need a fast white-background marketplace image.Correcting, standardizing, and automating a large catalog**Claid**It focuses on enhancement, background work, and API-based image workflows.You are a solo seller processing only a handful of images per month.Putting clothing on diverse human models without a new shoot**insMind AI Virtual Model**It is designed for mannequin, ghost-mannequin, and flat-lay-to-model fashion imagery.You are selling non-apparel products such as furniture, food, or electronics.Creating a product image and the finished social post in one place**Canva AI Product Photos**You can generate the image inside a design workflow, then add copy, logos, and layouts.You need deep retouching control or a production-grade catalog pipeline.Making complex, pixel-level edits without losing control of the original file**Adobe Photoshop Generative Fill**It combines generative editing with selections, layers, reference images, and non-destructive workflows.You want the fastest beginner-friendly option with almost no learning curve.
## Before you choose a tool: use the “product truth” test
*The product should remain the same in every generated variation; only the setting, crop, and supporting elements should change.*
Every tool in this guide can make a visually attractive image. The harder question is whether the image remains truthful to the item you are selling.
Before publishing any AI-assisted product image, review it at 100% zoom and check the following five points:
Product-truth checkWhat to inspectWhy it matters**Shape and silhouette**Corners, handles, sleeves, straps, closures, and proportionsAI may subtly bend or invent physical details.**Brand and label accuracy**Logos, claims, ingredient lists, sizes, and packaging textUnreadable or altered text can create compliance and trust problems.**Color accuracy**Product color, material finish, and shade variationA warm AI scene can make a white product look cream or a blue product look teal.**Included components**Caps, cables, accessories, product count, and bundle contentsAI sometimes adds or removes objects in a scene.**Believable contact**Shadows, reflections, surface contact, and scaleA product that appears to float looks artificial and may hurt perceived quality.
This check is the most important step in the entire workflow. Use AI to create the setting, improve the lighting, or expand the canvas. Do **not** allow it to change the product itself unless the image is clearly conceptual and not being used to represent a purchasable item.
## The 7 best AI product photography tools
### 1\. Photoroom: best for fast catalog images and day-to-day e-commerce work
[Photoroom](https://www.photoroom.com/) is the best starting point for most small e-commerce businesses because it solves the unglamorous but essential work first: removing backgrounds, cleaning an image, resizing it for a channel, and producing consistent variations across many SKUs.
Its product-photography workflow includes background removal, AI background generation, lifestyle images, image enhancement, resizing, batch editing, brand-kit features, and automation options.\[1\] That combination matters more than a single impressive AI generation. A seller needs a reliable way to prepare a product for a listing, a marketplace thumbnail, an ad creative, and a social post—not just one attractive hero image.
**Choose Photoroom when:**
- You photograph products with a phone and need polished results quickly.
- You have a growing catalog and need the same treatment applied across many images.
- You sell on marketplaces where clean backgrounds and consistent crops matter.
- You want a practical mobile-first workflow rather than a design-heavy interface.
**Watch out for:** Lifestyle images still need a product-truth review. AI backgrounds are useful for creativity, but the final output should never hide key product features or make dimensions ambiguous.
**Best workflow:** Photograph the item in even daylight → remove the background → create a clean primary listing image → generate two lifestyle variants → export platform-specific crops.
### 2\. Pebblely: best for lifestyle scenes that do not look like a plain cutout
[Pebblely](https://pebblely.com/) is built around a specific e-commerce problem: you already have a clean product image, but it looks flat, generic, or disconnected from the lifestyle you want to sell. It generates varied product photography scenes, including backgrounds, surfaces, and contextual settings, from a product image and prompt.
This makes Pebblely particularly useful for beauty, candles, food packaging, home goods, jewelry, and similar items that benefit from mood and context. It is often a better choice than a general image generator when you need multiple seasonal or campaign concepts from the same product cutout.
**Choose Pebblely when:**
- Your original product photo is already clean but needs a believable environment.
- You need a spring, holiday, outdoor, editorial, or premium-studio variation without arranging a physical set.
- You need several creative directions to test in paid social or email campaigns.
**Watch out for:** Do not use a heavily generated lifestyle scene as the only listing image. Shoppers should still be able to see an accurate, unobstructed product shot elsewhere on the product page.
**Useful prompt pattern:**
> *\[Product\] on \[surface\], in \[environment\], \[lighting direction\], \[mood\], \[camera framing\]. Keep the product’s original shape, label, color, and proportions unchanged.*
For example: *“Amber glass skincare jar on light travertine in a calm bathroom, morning window light from the left, soft realistic shadow, editorial product photography. Keep the original jar label, lid, color, and proportions unchanged.”*
### 3\. Flair: best for brands that need art direction rather than random generations
[Flair](https://flair.ai/) is the better option when your team does not want to accept whatever scene an AI happens to generate. Its workflow is based on a drag-and-drop canvas: you can stage props and backgrounds, then use AI to bring the composition to life. Flair also highlights on-brand content generation, AI ad creation, custom AI human models, team collaboration, and API access.
The key advantage is control. A brand manager can decide where the product sits, how much empty space is available for text, and which visual elements belong in the scene before generating the final image.
**Choose Flair when:**
- Your visual identity uses recurring props, colors, or compositions.
- You need image space for headlines, badges, or offer messaging.
- Multiple people must review and produce assets in a consistent campaign style.
- You want to create ads and product scenes from the same brand system.
**Watch out for:** Flair is more powerful than a one-click tool, but that also means it works best when someone takes ownership of the visual direction. It is not the fastest option for processing 500 plain marketplace listings.
### 4\. Claid: best for image quality, standardization, and API-scale production
[Claid](https://claid.ai/) is designed for the operational side of product photography. It offers image enhancement, background removal and generation, resizing, and API-based workflows for e-commerce imagery. Its positioning makes it especially relevant when quality and consistency must be applied across a large number of images, including seller-uploaded photos that were not captured under ideal conditions.
For a marketplace, multi-vendor store, or large catalog, the challenge is rarely “Can we make one nice-looking image?” The challenge is “Can we make every image meet the same visual standard without assigning a designer to each one?” Claid is aimed at that problem.
**Choose Claid when:**
- You need to improve poor or inconsistent source images.
- You receive vendor imagery with uneven lighting, low resolution, or inconsistent dimensions.
- You need automation through an API or a repeatable operations workflow.
- Your catalog contains enough images that manual editing is becoming a bottleneck.
**Watch out for:** Automation is valuable only after you define a clear image standard. Decide your background style, crop ratio, naming convention, and approval rules before processing thousands of assets.
### 5\. insMind AI Virtual Model: best for apparel, mannequins, and flat lays
Fashion has a different product-photography problem from most other categories. Customers need to understand fit, drape, scale, and styling. A flat lay can show a garment, but an on-model image helps shoppers imagine it in use.
[insMind AI Virtual Model](/products/ai-virtual-model-generator-turn-mannequins-into-real-models) turns mannequin, ghost-mannequin, and flat-lay apparel images into photos with virtual human models. It is aimed at preserving garment textures, prints, silhouettes, and other original details while allowing varied model presentation.
**Choose insMind when:**
- You sell apparel and need on-model images without scheduling a shoot for every SKU.
- You want to localize a collection with different model appearances.
- You are testing product demand before investing in a full editorial shoot.
**Watch out for:** Apparel accuracy needs the strictest review. Inspect neckline shape, sleeve length, fabric pattern, logo placement, buttons, seams, and hemline before publishing. If the garment is altered, do not use the image as a primary product representation.
### 6\. Canva AI Product Photos: best when the image must become a complete marketing asset
[Canva’s AI Product Photos app](https://www.canva.com/apps/AAGXp9Q0Bd4/ai-product-photos) lets users upload a product image, enter a prompt, and create a new product photo from inside Canva. Its value is less about creating the most sophisticated raw image and more about eliminating handoffs.
After generating a product image, you can immediately build a social graphic, email banner, story, ad layout, or sale announcement around it. This makes Canva a sensible choice for solo founders and social teams who care about speed from product photo to finished campaign asset.
**Choose Canva when:**
- You already create social posts and ad layouts in Canva.
- You need to combine a product image with typography, logos, offers, and templates.
- You want a simple workflow for smaller campaign batches.
**Watch out for:** For product listings, always save a separate clean source image. A visually effective social creative is not necessarily appropriate as the product’s primary catalog photo.
### 7\. Adobe Photoshop Generative Fill: best for advanced retouching and non-destructive control
[Adobe Photoshop Generative Fill](https://www.adobe.com/products/photoshop/generative-fill.html) is the right choice when automated tools almost work—but not quite. It allows users to select specific areas, add or remove content with a prompt, generate variations, use a reference image, and keep generative changes on separate layers for non-destructive editing.
That level of control matters when you need to preserve a hero product image and only fix a small detail: extending a backdrop to a new aspect ratio, removing a distracting object, adding realistic negative space for a campaign headline, or repairing a broken shadow.
**Choose Photoshop when:**
- Product accuracy is high stakes and you need manual control.
- You are creating premium launch images or paid campaign creative.
- Your team already knows basic masking, selections, and layers.
- You need to adapt one approved scene into several aspect ratios without rebuilding it.
**Watch out for:** Photoshop is not a shortcut for weak source photography. It is a powerful finishing environment, but the best results still start with a sharp, well-lit original product image.
## The practical workflow: create four useful images from one product photo
A common mistake is trying to make one AI-generated image do every job. Instead, create a small image system for each priority product.
Image typePurposeWhat it should showBest tools**1\. Truth image**Primary product page and marketplace listingUnobstructed product, accurate color, clear label, simple backgroundPhotoroom, Claid, Photoshop**2\. Detail image**Product page persuasionTexture, material, scale, closure, key feature, or before/after proofPhotoroom, Photoshop**3\. Lifestyle image**Brand pages, social, email, and adsThe product in an aspirational but believable settingPebblely, Flair, Canva**4\. Campaign variant**Testing offers, seasons, or audiencesSame product with changed scene, crop, message space, or modelFlair, Canva, insMind, Photoshop
This approach makes your visuals more useful and protects your credibility. Your **truth image** helps the customer decide. Your **lifestyle image** helps the customer desire. Your **campaign variant** helps your marketing team test. None of these images should replace the others.
*Create one repeatable workflow before you create hundreds of image variations.*
## A repeatable five-step process for small businesses
### Step 1: capture a better source image before opening an AI tool
Use even light, a clean lens, and a plain background. Place the product far enough from the background to avoid a hard shadow merging with its edge. Capture at least three angles: front, three-quarter, and close-up detail.
AI can add a scene. It cannot reliably reconstruct a label that is already blurry or restore product details that were never captured.
### Step 2: build one accurate cutout first
Remove the background and inspect the edge before generating any lifestyle scenes. The quality of the cutout affects every image you create later. Correct small edge problems now rather than generating ten variations with the same flaw.
### Step 3: create scenes with constraints, not only aesthetics
Use prompts that describe the setting *and* protect product truth. Add the following constraint to every prompt:
> *Preserve the original product shape, color, label, logo, materials, and proportions. Do not add accessories or change packaging.*
Then add specific details about light, surface, and composition. A constrained prompt produces fewer unusable generations than a vague one.
### Step 4: run the product-truth checklist before exporting
Do not review only the first image that looks good on a small screen. Zoom in and check labels, edges, color, product count, and shadows. Ask a second person to compare the final image with the physical item if the product is high value or regulated.
### Step 5: export for the channel, not just for your desktop
Plan the crop before generating. A product image intended for a square Instagram post should have enough surrounding space to survive a 4:5 ad crop or a horizontal email banner. Use a clean file naming system such as:
`product-name_angle_scene_channel_version.jpg`
For example:
`candle-amber-jar_front_travertine-instagram_v03.jpg`
## Three product categories where AI can save the most time
### Beauty, skincare, candles, and packaged goods
These products are ideal for AI lifestyle scenes because the physical item is compact and easy to photograph cleanly. The highest-value AI contribution is often seasonal variation: one approved product photo can become a summer scene, a holiday scene, a spa scene, or a minimalist studio scene.
The risk is label distortion. If the product has regulatory information, ingredients, or small print, use a clear truth image on the product page and reserve AI lifestyle images for supplementary marketing.
### Apparel and accessories
AI can reduce the cost of creating on-model imagery, particularly for long-tail sizes, colors, and test collections. Yet apparel is also where inaccurate images can be most damaging. Review garment construction and fit closely; a beautiful image that shows the wrong neckline or sleeve shape is not useful for conversion.
### Large marketplaces and multi-SKU catalogs
For large catalogs, the biggest win is not exotic creativity. It is consistency. Standardized crops, backgrounds, lighting, image dimensions, and quality checks can improve browsing and reduce manual production work. Prioritize tools with batch processing or API workflows before investing in complex creative generation.
## Common mistakes that make AI product photography look cheap
MistakeWhy it hurtsBetter approachGenerating a scene before making a clean cutoutEdge problems multiply across every variation.Clean the source image first.Using a dramatic image as the only product listing photoCustomers cannot inspect the actual item clearly.Pair lifestyle images with an accurate truth image.Writing vague prompts such as “luxury product photo”The AI has too much room to invent irrelevant details.Specify surface, environment, light, framing, and constraints.Ignoring inaccurate text or logosSmall errors make a product feel untrustworthy.Check at 100% zoom and replace the image if details are altered.Treating every product category the sameFashion, jewelry, furniture, and skincare have different accuracy risks.Choose tools and review criteria by category.Generating dozens of variations without a visual briefYou create more assets but not a repeatable brand system.Define colors, surfaces, light, crop, and use case first.
## Frequently asked questions
### Can AI product photography replace a professional photoshoot?
For many everyday catalog images, social assets, and campaign variations, AI can significantly reduce the need for repeated shoots. It does not replace a professional shoot when you need complex human interaction, high-end editorial art direction, precise product detail, or legally sensitive claims. The best approach is often hybrid: shoot a small library of accurate source images, then use AI to create more variations from those approved assets.
### Can I use AI-generated product images commercially?
Commercial-use terms depend on the tool, plan, model, and your source material. Read the current terms before publishing paid ads, print work, or large campaigns. Regardless of licensing, do not use an AI image that materially misrepresents the physical product.
### What is the best AI product photography tool for Shopify?
For most Shopify merchants, Photoroom is the easiest general starting point because it handles product cleanup, backgrounds, resizing, and batch workflows. Add Pebblely when you need more creative lifestyle content. If you are building a more art-directed brand, add Flair or Photoshop for campaign work.
### Which tool is best for Amazon listings?
Start with a clean, accurate, policy-compliant product image rather than a heavily generated lifestyle image. Photoroom, Claid, and Photoshop are generally better suited to producing and checking the clean source assets that marketplace listings require. Review the marketplace’s current image requirements before uploading.
### How do I keep AI from changing my product?
Start with a high-quality, well-lit product image. Use tools that preserve a source cutout, add a clear preservation constraint to your prompt, and inspect the final image at full size. If the AI changes a logo, shape, or important detail, discard that version rather than trying to explain it away.
## Explore more tools for your image workflow
Product photography is only one part of an e-commerce visual workflow. Browse PickApps for more options in [Product Photography](/categories/product-photography), [AI Image Generators](/categories/ai-image-generator), [AI Photo Editors](/categories/ai-photo-editor), and [Background Removers](/categories/background-remover).
---
### What Is Omoggle? The Viral AI PSL Mog Battle Game Explained
URL: https://pickapps.org/blog/what-is-omoggle-ai-psl-face-rating
Description: Omoggle is a viral 1v1 mog battle game mixing Omegle-style random video chat, PSL-style face rating, ELO rankings and streamer culture. Learn how it works, what PSL means, safety notes and related alternatives.
*Last updated: May 13, 2026*
Omoggle is a viral 1v1 mog battle game where users enter a live camera-based arena, get compared through PSL-style face-rating mechanics, and compete for points or ranking. It combines the random-video energy of Omegle-style chat, the competitive ladder of online games, and the internet slang of mogging, looksmaxxing, and PSL scores.
This guide explains what Omoggle is, how it works, what mogging and PSL rating mean, how Omoggle differs from Omegle and Mog Omegle, and what safer related tools you can explore if you are curious about the trend without jumping into a live random video arena.
This page is an independent guide from PickApps. It is not affiliated with, endorsed by, or operated by Omoggle.
## Quick Summary
Omoggle is a live 1v1 face-off arena. Users enter with a camera, pass through a camera check, see or run a PSL-style scan, and compete in short mog battles. The public [Omoggle homepage](https://omoggle.com/) presents the experience around a camera check, Solo PSL Scan, and compete-and-climb loop.
Omoggle is not the same as Omegle. Omegle was mainly random text or video chat with strangers, and the original Omegle site now shows a shutdown note. Omoggle adds a competitive layer: face-rating language, match outcomes, ELO-style ranking, leaderboards, and streamer-friendly reactions.
Omoggle is also different from Mog Omegle. People searching for "Mog Omegle" may be looking for photo-based AI PSL comparison tools where two uploaded faces are compared through a radar chart, score, verdict, or share card. Omoggle is more live, random, and video-based.
The safest way to treat PSL scores is entertainment-only. A face-rating score is not medical advice, psychological advice, romantic advice, or a measure of personal worth.
## What Is Omoggle?
Omoggle is a live 1v1 mog battle game built around camera-based matchups. On its public homepage, Omoggle presents a flow that includes a camera check, a Solo PSL Scan, and a compete-and-climb loop with rankings or ladder mechanics.
The word "mog" means to outshine, overpower, or dominate someone, often in appearance or social presence. In Omoggle's context, to "mog" someone means to win a face-off or appear to score better according to the platform's game mechanics, audience reaction, or ranking system.
That format is why Omoggle spread quickly in streamer culture. A match is simple to understand: two people appear, a score or comparison happens, someone wins, and the clip is easy to react to. The same simplicity also creates risk, because a live face-rating game can turn insecurity, appearance judgment, and stranger-video exposure into public content.
## How Does Omoggle Work?
The basic Omoggle flow can be understood in four steps:
1. Enter the arena.
Users land on the site and are pushed toward a camera-based experience.
2. Complete a camera check.
Omoggle's public page describes a camera check before the arena. It also says the experience is restricted to adults, but its public copy frames that as an 18+ acknowledgement rather than legal ID verification.
3. View or run a Solo PSL Scan.
The site describes a PSL-style scan as part of the experience. Based on the public product framing and current reporting, this should be treated as algorithmic entertainment, not objective science.
4. Compete and climb.
Users can be matched into short face-offs, with wins, losses, points, ELO-style progression, or leaderboards forming the game loop.
That is the key difference from a normal random chat site. The chat is not the main hook. The scoreboard is.
## What Does Mogging Mean?
Mogging is internet slang for outshining or dominating someone. It is often used around looks, facial structure, height, physique, style, confidence, or perceived social status.
In newer meme and streamer culture, mogging is sometimes used ironically. In looksmaxxing communities, it can be treated more seriously. Both contexts matter. The term may look like a joke, but it can also carry body-image pressure, ranking language, and harsh comparison.
In Omoggle, mogging becomes a game mechanic. Two users are compared in a short face-off, and one is treated as the winner. That makes the concept instantly understandable, but also more emotionally loaded than a normal chat room.
## What Is PSL Rating?
PSL is an appearance-rating shorthand used in looksmaxxing and mogging communities. In Omoggle-style content, PSL is usually connected to face-analysis terms such as symmetry, jawline, skin quality, eye area, harmony, canthal tilt, and other facial-ratio language.
The important caveat: PSL rating is internet scoring culture, not objective proof of attractiveness or worth. Some platforms wrap PSL language in AI or facial-analysis terminology, which can make the score feel more scientific than it should.
For any Omoggle or AI face-rating page, the safest framing is:
PSL is an entertainment-oriented face-rating shorthand used in mogging and looksmaxxing communities. It should not be used to judge someone's health, personality, dating prospects, future, or value as a person.
## Omoggle vs Omegle vs Mog Omegle
| Feature | Omoggle | Omegle | Mog Omegle / AI PSL compare tools |
|---|---|---|---|
| Main idea | Live 1v1 mog battle arena | Random stranger chat | Photo-based face comparison |
| Format | Camera-on face-off | Text/video chat | Upload or compare images |
| Scoring | PSL-style scan, match results, rankings | No native face score | Scores, radar chart, verdict, share card |
| Culture | Mogging, PSL, stream clips, leaderboards | Anonymous chat | AI face rating and meme cards |
| User intent | Compete, react, rank, clip | Talk to strangers | Compare two faces or generate a shareable result |
| Main risk | Live strangers plus appearance judgment | Live stranger-video risk | Face-data, body-image, and sharing risk |
Omoggle is closer to a game than a chat room. Omegle was about meeting a random stranger. Omoggle is about being judged with or against a random stranger.
Mog Omegle is a different search intent. If someone searches "Mog Omegle," they may not want a live arena at all. They may want an upload-first AI comparison tool that creates a radar chart, verdict, score band, or downloadable card. That distinction is useful for directory sites like PickApps because users may want related tools without live random video.
## Why Is Omoggle Going Viral?
Omoggle went viral because it combines several high-retention internet ingredients:
- random strangers;
- live video;
- appearance scoring;
- competitive ranking;
- streamer reactions;
- Gen Z slang;
- controversial psychology;
- instant win-or-lose outcomes.
That mix creates clips. Clips create reactions. Reactions create search demand.
Reporting in May 2026 connected Omoggle's surge to streamer culture and Twitch discussion around randomized video chat content. [Dexerto](https://www.dexerto.com/twitch/what-is-omoggle-the-ai-face-rating-platform-taking-over-twitch-3360363/) described the platform as an AI face-rating trend taking over Twitch, while [The Guardian](https://www.theguardian.com/games/2026/may/10/mogging-gen-z-and-why-streaming-platform-twitch-hanged-rules-omoggle) covered the broader mogging and streamer-policy controversy.
The careful way to describe this is not that Twitch endorsed Omoggle. The safer and more accurate wording is that Omoggle became part of a broader discussion around randomized video chat content and platform enforcement, while platforms still reserve the right to enforce rules when harmful or prohibited content appears.
## Is Omoggle Safe?
Omoggle should be treated as an adult live-video and appearance-comparison platform. That does not automatically mean every use is harmful, but users should understand the risks before participating.
Potential risks include:
- being matched with strangers on live camera;
- appearance-based judgment;
- public embarrassment, harassment, screenshots, or clips;
- underage access concerns;
- body-image and self-worth pressure;
- biometric, face-data, or moderation-data questions;
- platform-rule risk for creators streaming randomized video content.
The official Omoggle homepage says face scanning is processed locally, but privacy claims should be read carefully. Local processing does not necessarily mean no account, match, saved report, moderation, or support data can ever be stored. Review the current [Omoggle Privacy Policy](https://omoggle.com/privacy) and [Omoggle Terms of Service](https://omoggle.com/tos) before using the service.
If you are only curious about the trend, you do not need to join a live video arena. You can read explainers, compare safer categories, or use tools that do not require random stranger matching.
## Safer Related Tools to Explore
If you want the Omoggle-style concept without live random video, consider these related categories:
If your goal is not a mog battle or PSL score, but a calmer photo-based proportion check, you can try PickApps' [Face Shape Detector](/tool/face-shape-detector). It focuses on a closest supported face-shape match from a front-facing photo, rather than ranking people against each other.
| Category | What it helps with | Safer angle |
|---|---|---|
| Face shape detector | Photo-based face proportion reference | Use a non-competitive closest-match tool instead of live random matching |
| AI face rating tools | Entertainment-style face analysis | Use uploaded photos instead of live random matching |
| Profile photo analyzers | Feedback for profile pictures | Focus on photo quality, lighting, and presentation |
| Camera check tools | Test webcam framing and quality | No stranger matching required |
| Mog battle card generators | Create meme-style comparison cards | More controlled sharing |
| Omegle alternatives | Random chat or video alternatives | Compare moderation and privacy before joining |
| Meme card generators | Make shareable reaction images | Avoid using real people without consent |
PickApps can help you compare related AI tools, video tools, profile photo tools, and creator utilities before choosing a platform.
## FAQ
### What is Omoggle?
Omoggle is a live 1v1 mog battle game where users compete in camera-based face-offs with PSL-style scoring, match outcomes, and ranking mechanics.
### Is Omoggle the same as Omegle?
No. Omegle was mainly a random chat platform. Omoggle adds a competitive appearance-scoring layer with face-off matches, ranking culture, and mogging terminology.
### What is Mog Omegle?
Mog Omegle usually refers to a related search intent around AI PSL comparison tools. These tools often compare uploaded photos and generate scores, verdicts, radar charts, or share cards. That is different from a live random-video arena.
### What does mogging mean?
Mogging means outshining or dominating someone, often in looks, physique, facial structure, style, or perceived social presence.
### What is PSL rating?
PSL is an internet face-rating shorthand used in mogging and looksmaxxing communities. It should be treated as entertainment, not as objective science or personal-worth advice.
### Should you use Omoggle safely?
Omoggle involves live video, strangers, and appearance-based judgment, so users should be cautious. Minors should avoid it, and adults should understand the privacy, safety, moderation, and emotional risks before participating.
### What are Omoggle alternatives?
Alternatives include AI face rating tools, photo-based mog battle generators, profile photo analyzers, webcam test tools, meme card generators, and other random video chat platforms with clearer safety controls.
## Final Thoughts
Omoggle is not just another Omegle clone. It is a snapshot of a newer kind of internet trend: random video, AI-flavored scoring, competitive ranking, streamer reactions, and meme language fused into one fast-moving arena.
For some people, it is a joke. For others, it can be uncomfortable or harmful. Either way, the search interest is real.
If you are exploring Omoggle because you want to understand the trend, start with the basics: learn what mogging means, understand PSL rating, compare Omoggle with Omegle and Mog Omegle, and look at safer alternatives before putting your face into a live competitive arena.
This page is an independent PickApps guide and directory resource. It is not affiliated with, endorsed by, or operated by Omoggle.
---